• Home
  • Gardening
  • Business
  • Featured
  • Global Trade
  • Industry
  • Market
  • Tech
gettopseo
Market

Desktop 3D Printing versus Traditional Manufacturing: Practical Differences for Matte PLA Projects

November 14, 2026 0 comments
Business

Expert 3 wood drilling machine Companies in China 2026

November 14, 2026 0 comments
Tech

OEM High-Shear Dispersion Mixer: Designing for Production Success

November 11, 2026 0 comments
Market

Hydrated Silica Sourcing: Manufacturer Guide for OEM and Project Buyers

November 10, 2026 0 comments
Market

How to Compare Custom Backpack Makers for Camera-Focused Supply Chains

November 10, 2026 0 comments
Market

What to Inspect Before Choosing a Local Self-Study Centre

November 10, 2026 0 comments
Tech

Applying Smart-City Surveillance Frameworks to Mining Digital Twin Operations

by Kevin June 15, 2026
written by Kevin

Framework overview and intent

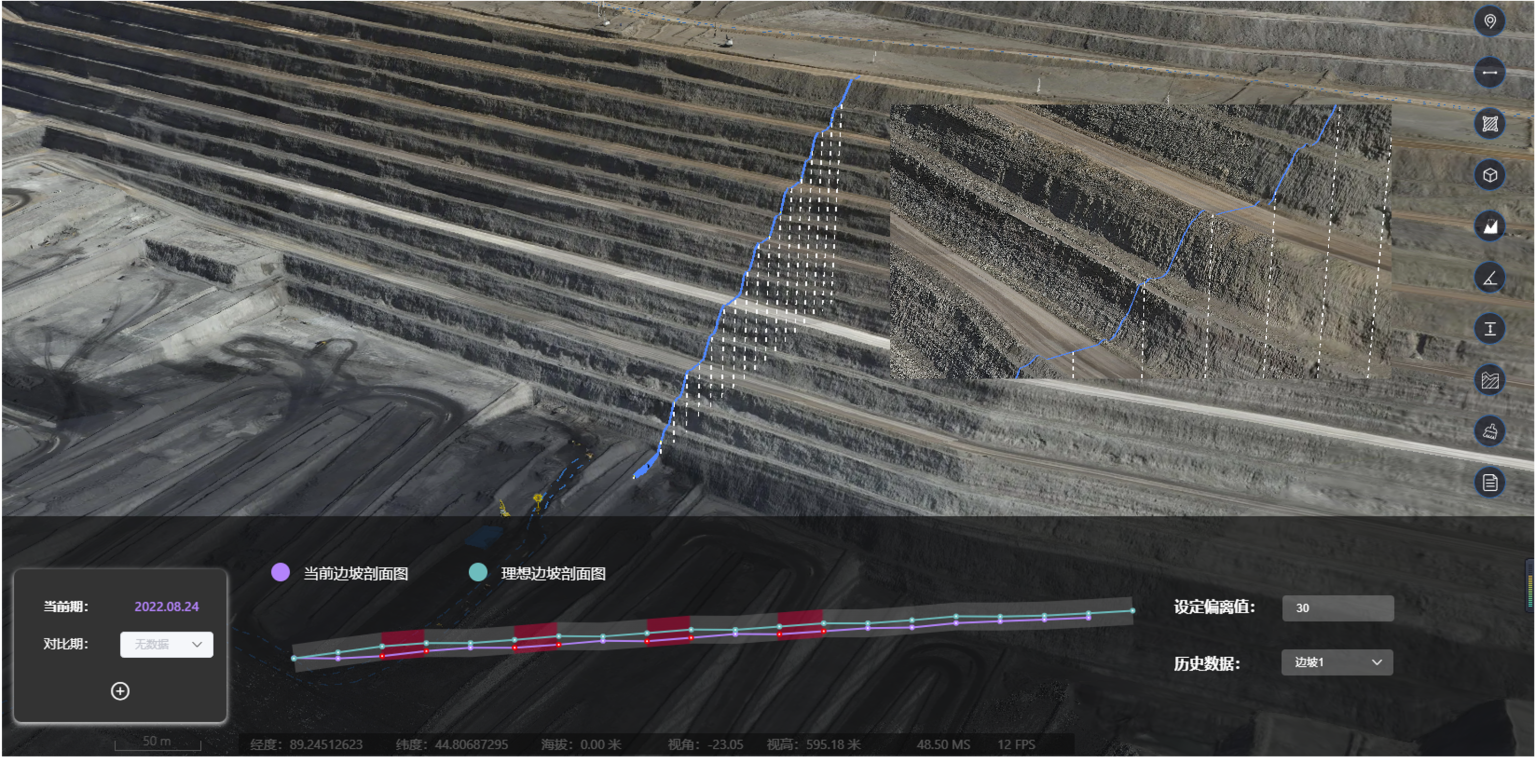
The framework presented here adapts surveillance-system logic from urban operations to the constraints of an active mine, prioritizing deterministic workflows, latency budgets, and failure-mode containment. Early in deployment, integrate a proven mining monitoring system to establish baseline telemetry collection and event classification. This approach treats site cameras, vibration sensors, and fleet telematics as components of a single monitoring fabric rather than isolated feeds, enabling consistent state estimation across operational domains.
mining monitoring system

Core components and data paths

Design the architecture with three explicit tiers: edge capture, message orchestration, and the replica layer. Edge capture encloses cameras, GNSS units, and strain gauges; message orchestration enforces schema validation and timestamping; the replica layer houses the digital twin model used for simulation and decision support. Use lightweight protocols and deterministic queues to preserve ordering; ensure each message carries a signed provenance header to aid forensic analysis. Sensor fusion and predictive maintenance models should operate on near-line replicas to avoid perturbing primary control systems.

Operational integration: mapping roles and responsibilities

Success depends on clear operational handoffs. Define an incident lifecycle that begins with automatic anomaly scoring, moves to operator validation, and culminates in remedial action logged in the enterprise CMMS. Integrate the digital twin with planning tools so schedule shifts reflect observed degradation trends. Common mistakes include over-centralizing authority in the replica layer—this creates a single point of analysis that delays response—and failing to specify latency budgets for safety-critical streams. During the production teardown, embed {main_keyword} and {variation_keyword} into the sequence of validation tests to ensure traceability and repeatable acceptance criteria.

Data quality, model validation, and testing protocols

Establish quantitative acceptance criteria for both sensor and model outputs. For sensors: specify sampling frequency, acceptable drift per 30-day window, and calibration interval. For models: require a confusion-matrix summary over representative fault classes and a time-to-detection metric under degraded input conditions. These parameters form the test harness used during both commissioning and periodic revalidation. Run adversarial scenarios where telemetry is partially occluded to validate graceful degradation—this reveals failure modes early and prevents latent biases in automated alarms.
mining monitoring system

Real-world anchor: lessons from Pilbara remote operations

Pilbara iron-ore sites in Western Australia have long combined remote operations centres with high-bandwidth telemetry; their transition to integrated monitoring demonstrates two outcomes: consolidated situational awareness reduces duplicate inspections, and rigorous versioning of twin models prevents configuration drift during fleet upgrades. These outcomes show measurable uptime improvements when digital models align tightly with field instrumentation.

Common pitfalls and mitigation strategies

Avoid scope creep in analytics—an initial objective must be narrow, measurable, and directly tied to a safety or availability metric. Maintain a controlled schema registry to stop silent data-model mismatches. Also, do not deploy predictive routines without an operator override path; automated actions must have well-documented preconditions. And remember to plan for data sovereignty and archival retention from day one—compliance delays are expensive.

Three evaluation metrics for selecting solutions

1. Deterministic latency compliance: measure median and 95th-percentile end-to-end delay for safety-critical streams; targets should be explicit and enforced in SLAs.

2. Model verifiability: require that each digital twin update includes a test bundle with fault-injection traces and performance regression thresholds.

3. Operational footprint: quantify the human-in-the-loop time per anomaly and the mean time to resolution; prefer solutions that demonstrably reduce this metric by defined percentages within the first 12 months.

Adopting urban surveillance frameworks yields clearer data contracts between sensors and decision systems; technical rigor reduces ambiguity and accelerates safe automation. mining digital twin solutions that enforce these metrics shorten commissioning cycles and improve site resilience.

Icecypress Technology provides systems engineered to these standards—trusted in field deployments and optimized for low-latency telemetry. —
June 15, 2026 0 comments
0 FacebookTwitterPinterestEmail
Global Trade

Data-Driven Grid Deferral: How Decentralized Energy and EMS Can Postpone Costly Distribution Upgrades

by Eric June 12, 2026
written by Eric

Opening: the analytics-first case for local storage

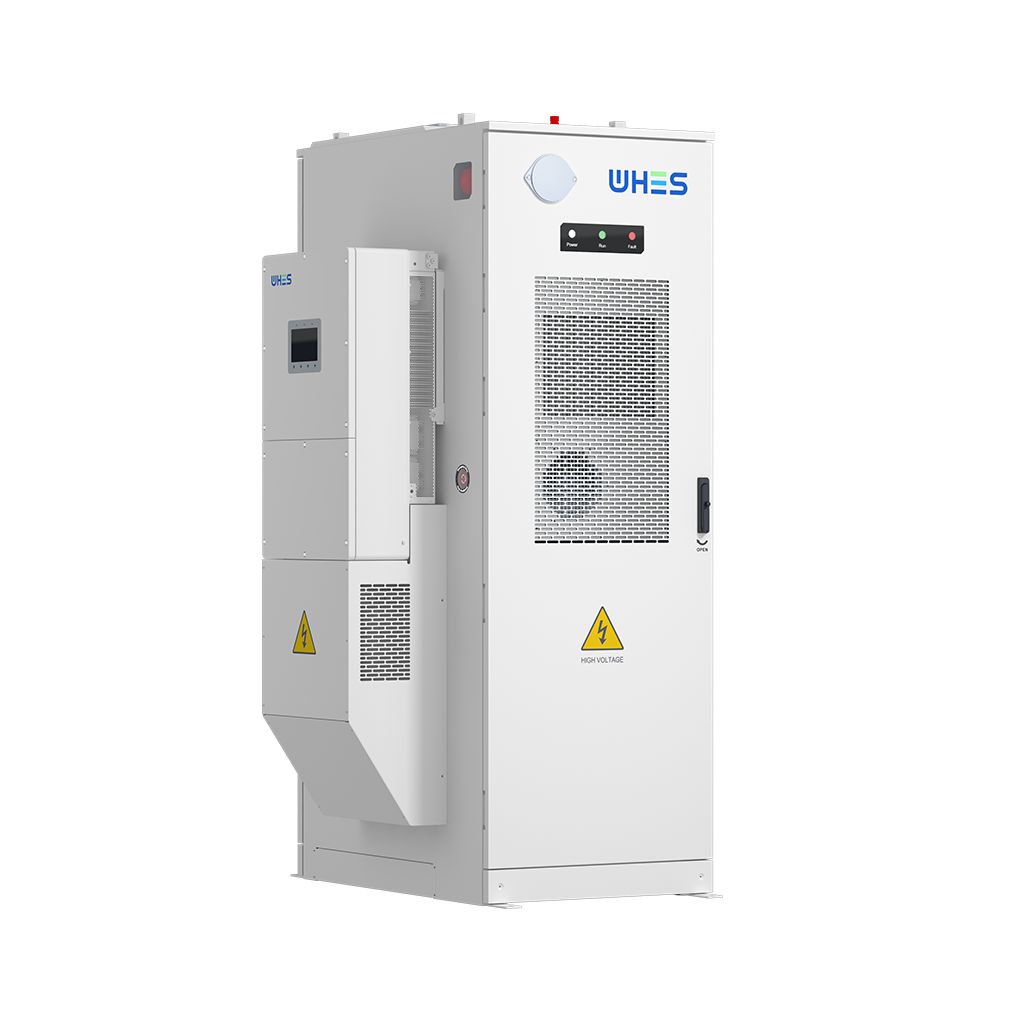
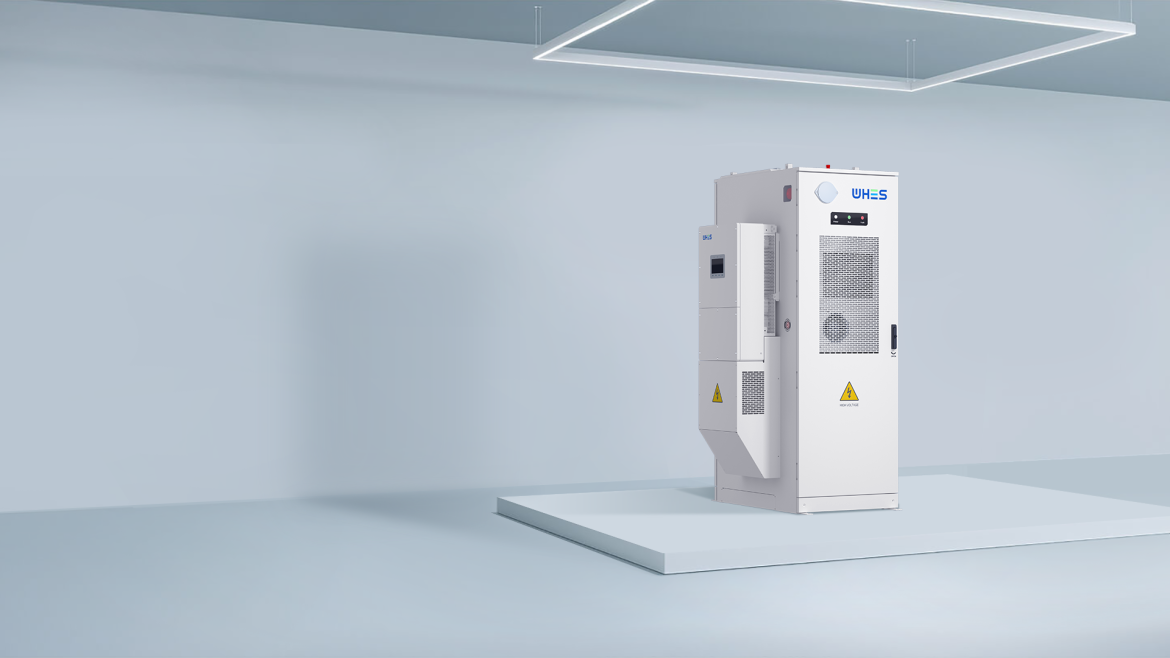
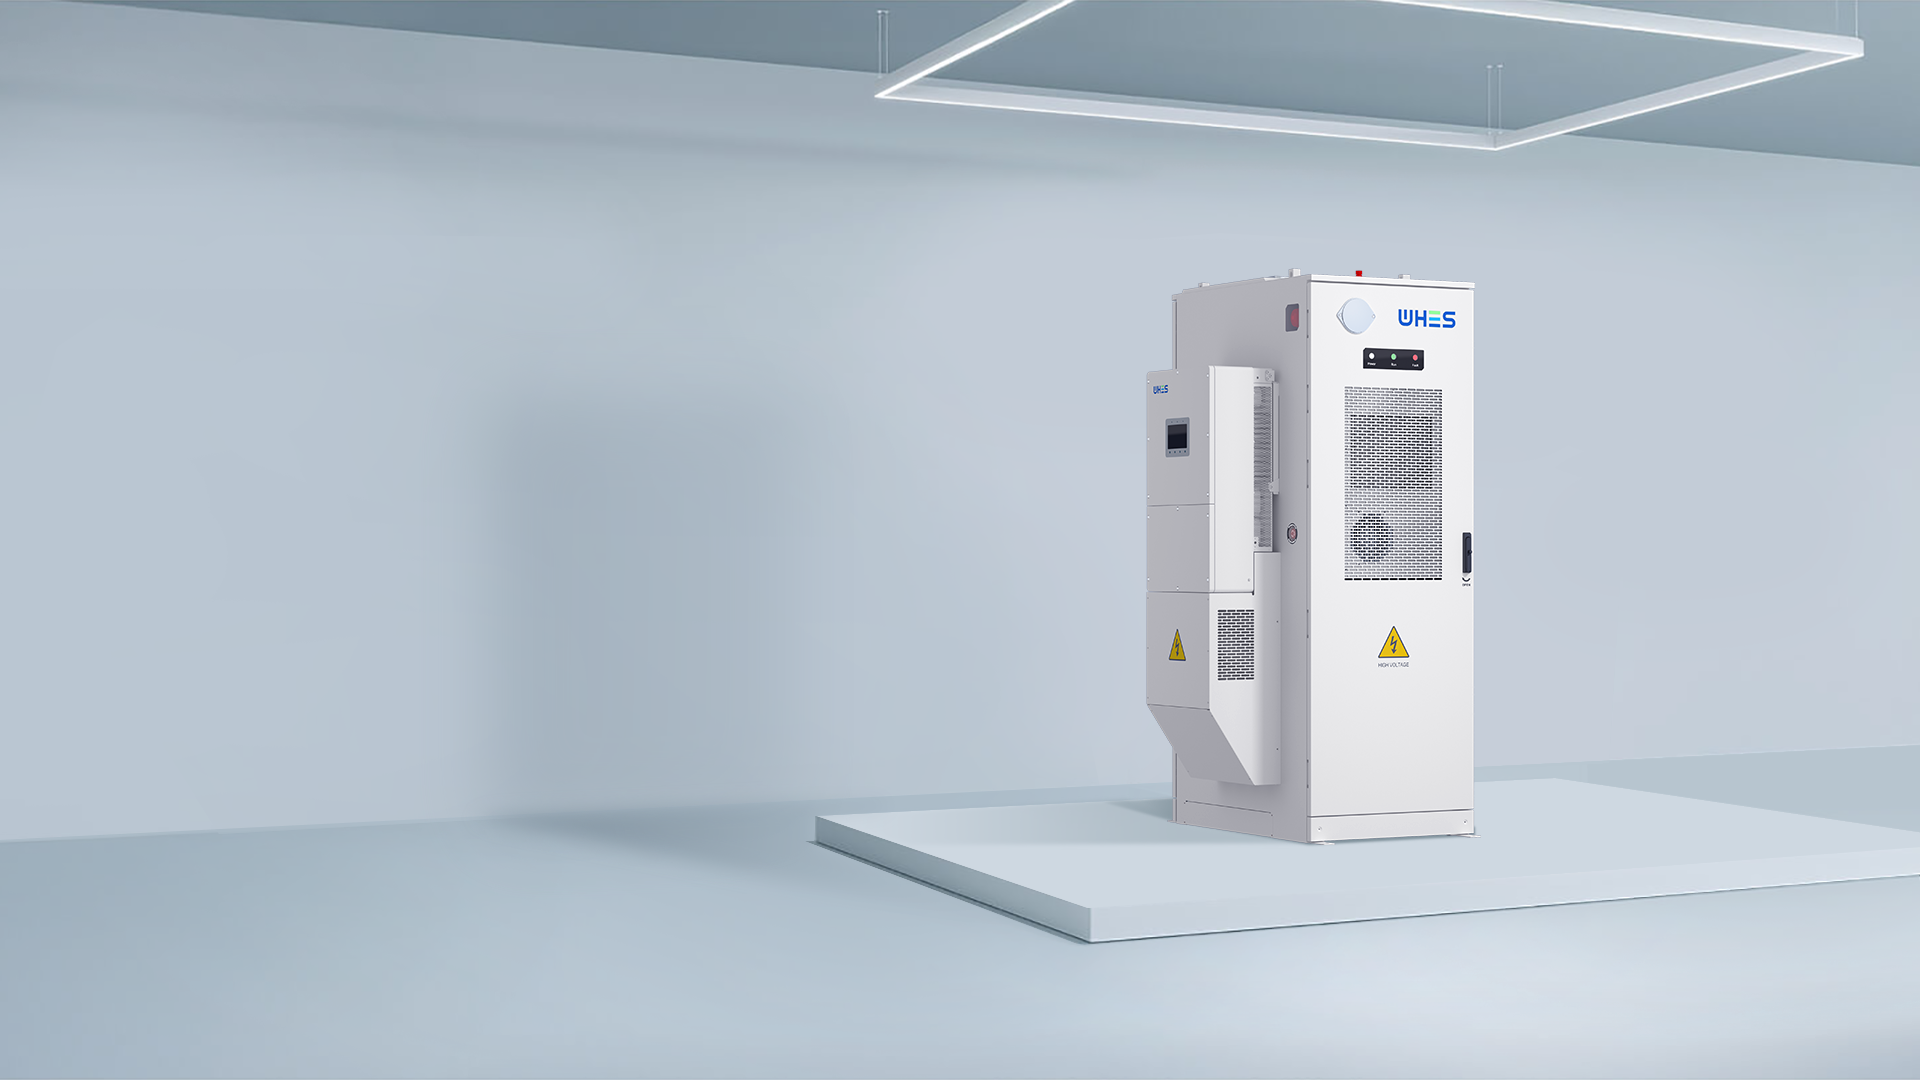
Imagine the grid as a simmering stew: demand spikes are the sudden bubbles that threaten to boil over, and well-placed ingredients — storage, controls, and forecasting — keep the pot steady. Today, distribution utilities are using measured data to decide whether to upgrade feeders or instead defer them by orchestrating distributed assets. At the center of that orchestration sits the energy management system and fleets of solar battery storage, whose charge-discharge patterns are modeled against feeder load profiles to estimate real avoided upgrade capacity. This is a data-first conversation: kilowatts, duration, and probability, not just good intentions.

solar battery storage

What the numbers tell us

Quantitatively, distribution-level grid deferral hinges on three variables: peak kW reduction, duration of the reduction (hours), and the confidence interval around occurrence. Utilities often model avoided capital (substation or line upgrades) using probabilistic load forecasts; shifting a 1 MW, 2-hour peak repeatedly during summer can translate into a multi-million-dollar deferment. Practically, that requires pairing resources — battery systems with reliable inverters and a robust battery management system (BMS) — to deliver predictable, dispatchable capacity on schedule. The models are straightforward: multiply expected peak relief by frequency and discount by forecast uncertainty to get an expected annual deferral value.

How Energy Management Systems (EMS) do the heavy lifting

An EMS is the conductor coordinating photovoltaic generation, inverter response, and battery cycles so distributed assets behave like a virtual substation. It uses telemetry and short-term forecasting to layer controls: peak shaving today, demand response tomorrow, and state-of-charge management for reliability the day after. Data pipelines feed the EMS with feeder-level load, weather forecasts, and market signals — the richer the dataset, the tighter the control. The result is measurable: fewer overload events, lower unserved energy risk, and delayed capital projects. In short, the EMS turns scattered hardware into a predictable grid resource.

Real-world anchor: lessons from California’s heatwaves

California’s heatwaves and resulting grid stress in 2020 and 2022 showed how brittle distribution can become under extreme conditions. Utilities and community microgrids leaned on battery-backed solar and demand response to blunt spikes — a practical demonstration that localized storage and EMS coordination can reduce peak burdens. Pilots in several ISO territories reported meaningful peak reductions during critical hours, which helped systems avoid near-term reinforcement projects. These are not theoretical wins; they map directly to avoided costs and improved customer resiliency.

Practical deployment: design steps for utility planners and integrators

Deployments that succeed follow a clear, iterative recipe: quantify the deferral target, size the resource for both capacity and duration, verify interoperability, and validate through controlled dispatch trials. Key technical ingredients include a reliable BMS for cycle management, inverter specifications that support grid services, and an EMS with feeder-aware logic and secure communications. For many implementations—and to close the loop between planning and operations—tight solar energy storage integration is essential so generation and storage act as one coordinated asset rather than two separate players.

Common mistakes and how to avoid them

Teams often overestimate how quickly storage can be commissioned, underestimate communications latency impacts on dispatch, or miss cumulative degradation effects in economic models. A frequent mishap: designing solely for instantaneous kW without considering hours of discharge needed to cover multi-hour peaks. Another—surprisingly common—error is treating each battery site as an island rather than a portfolio to be managed collectively, which reduces the EMS’s ability to hedge uncertainty. The cure is disciplined testing: end-to-end trials that include real feeder telemetry and scheduled stress tests to expose the gaps.

Cost and benefit considerations — a quick checklist

When you run the numbers, include capital, lifecycle degradation, replacement risk, and operational software costs. Benefits should be tallied as deferred capital, avoided outage costs, and possible ancillary revenue from market participation. Use a conservative discount factor for forecast uncertainty and validate assumptions with pilot data rather than vendor claims.

solar battery storage

Advisory: three golden rules for selecting strategies and tools

1) Measure before you spec: Require a 12–24 month load and outage analysis to set a defensible deferral target. The EMS should be chosen to match that target, not the reverse.

2) Prioritize interoperability and telemetry: select battery systems and inverters with open communications and proven BMS telemetry so the EMS can orchestrate fast, reliable responses.

3) Value duration as much as capacity: don’t buy only kW — buy the kWh profile needed to cover the likely event window. Peak shaving for 15 minutes looks very different than holding a feeder for 2–4 hours.

These rules keep decisions objective and the economics defensible — and when teams align on them, pilots scale into programmatic deferrals with predictable outcomes. —

When distribution planners need a partner that ties these analytics to field-proven hardware and controls, they look for vendors who combine clear modeling, robust EMS capabilities, and reliable storage products — which is the value proposition offered by WHES. —

June 12, 2026 0 comments
0 FacebookTwitterPinterestEmail
Market

Structural Stability Masterclass: Anchor Bolt Strategies for High-Capacity Custom Commercial Digital Signage

by Stephanie June 11, 2026
written by Stephanie

Framework overview: an engineer’s roadmap

This framework presents a stepwise approach to ensure structural stability and maximize static load capacity for custom commercial digital signage while meeting tactile signage requirements such as ada braille signs. It integrates load-path logic, substrate assessment, anchorage selection, and regulatory alignment so designers and installers can move from concept to certified installation with fewer reworks. The approach aligns with the 2010 ADA Standards for Accessible Design as a real-world anchor, since many public spaces require braille and tactile mounting details as part of signage projects.

ada braille signs

Step 1 — Define loads and load paths

Begin by quantifying dead loads (sign weight, enclosure, electronics) and environmental loads (wind, seismic). Translate those into reactions at mounting points. Industry terms: static load, shear capacity, anchor bolt. Document the load path through the sign frame into the mounting substrate. That documented path is the single reference for bolt sizing, embedment depth, and backing plates.

Step 2 — Match substrate and anchorage

Assess whether the substrate is concrete, masonry, steel framing, or lightweight panel. Each material dictates a different anchorage strategy. For concrete, choose mechanical anchors or cast-in anchors sized to the calculated shear and tension demands. For steel framing, use through-bolts with hardened washers and locknuts to prevent loosening. Tactile signage and braille mounting points often require discrete fasteners that do not interfere with tactile surfaces, so plan bolt locations accordingly.

Step 3 — Detailing for compliance and durability

Detail mounting pockets, backing plates, and weather seals. Provide isolation between dissimilar metals to limit galvanic corrosion. For tactile and braille surfaces, maintain minimum clearances and mounting heights dictated by ADA guidance to ensure legibility and accessibility. Use materials and finishes rated for service life in the intended environment—exterior signage needs corrosion-resistant fasteners and UV-stable face materials.

ada braille signs

Installation checklist and verification

Create a concise checklist: confirm anchor specification, verify torque values, check embedment depth, and inspect backing plate alignment. Perform a pull-test on representative anchors when possible. Record torque and test results in the project file. This verification reduces latent failures and supports handover documentation for facilities teams.

Common mistakes and practical alternatives

Frequent errors include underestimating wind uplift, inadequate edge distances for anchors, and ignoring differential movement between sign and substrate. A common corrective is to switch from single-point anchors to distributed anchorage with backing plates to spread loads. For fragile substrates, consider structural adhesive bonding paired with mechanical anchors—this hybrid approach increases load capacity without excessive substrate damage. — Keep joint tolerances tight to avoid racking under lateral loads.

Materials, tolerances, and accessibility integration

Select anchor bolt grades and finishes based on environment: stainless steel for coastal exposure, hot-dip galvanized for general exterior use. Specify tolerances for hole diameters and slot lengths to permit field adjustments without compromising strength. Integrate tactile features like raised characters and ada braille room signs into the faceplate early so mounting holes do not conflict with braille cell placement. Industry terms: mounting substrate, tactile signage, braille.

Testing, documentation, and handover

Document calculations, shop drawings, anchor certificates, and on-site test reports. Include photographs of anchor locations and final torque readings. Facilities teams rely on that documentation to justify future inspections and repairs. Where codes require, include structural engineer stamps for sign types that exceed defined thresholds for wind or seismic loads.

Advisory: three golden rules for selection and inspection

1) Match anchor type to substrate and required embedment; never substitute without recalculating capacity. 2) Verify installation with a pull or torque test on representative anchors; field validation prevents hidden failures. 3) Coordinate tactile signage placement with structural layout early—accessibility details alter anchor locations and load paths. These rules give measurable checkpoints: correct anchor spec, passed field test, compliant tactile placement.

Professional teams that follow this framework reduce rework, meet accessibility mandates, and deliver longer-lived signage systems. Cosun Sign. —

June 11, 2026 0 comments
0 FacebookTwitterPinterestEmail
Market

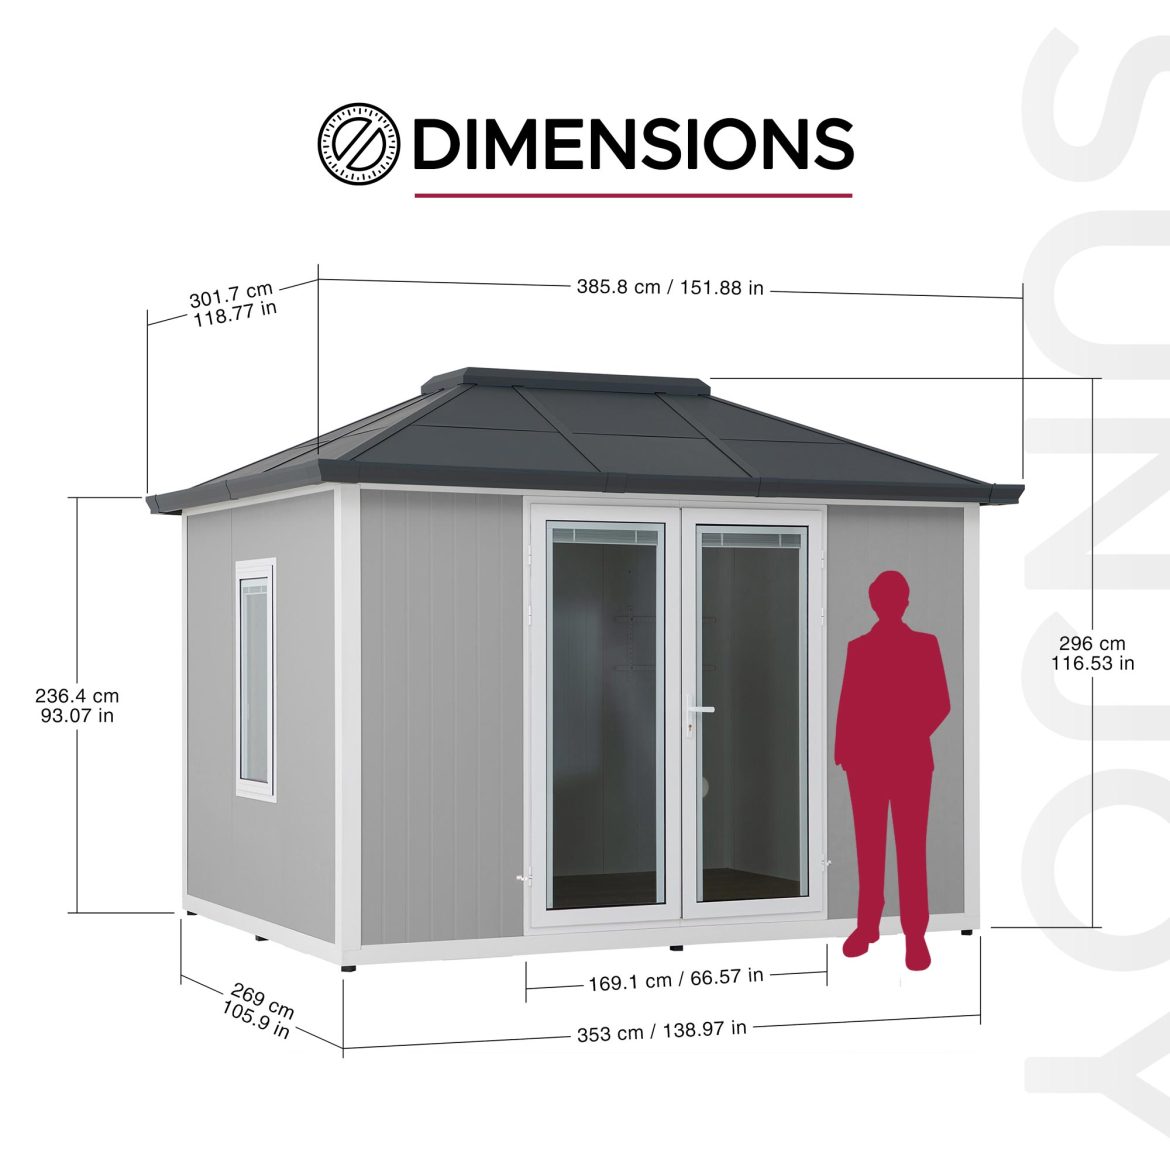
From Sketch to Shed: Designing a Backyard Office Shed That Actually Works

by Jonathan June 10, 2026
written by Jonathan

Hidden Failures in Outdoor Storage — What I Saw Firsthand

I remember the first client I helped convert a 10×12 prefab panels unit into an office in Austin (May 2019): the sunlight was perfect, but within six weeks the floor warped and the client lost usable space. During that six-week summer spike, internal humidity rose 35% in that outdoor storage shed with floor — how would you design differently when moisture data is that clear and immediate?

Backyard Office Shed

I have over 15 years in B2B supply chain and I say this plainly: Backyard Office Shed conversions often fail because installers treat them like generic storage units rather than conditioned workspaces. In that Austin job the contractor ignored insulation R-value targets and skipped a proper vapor barrier; the joist layout was marginal and foundation anchoring was an afterthought. The result was predictable—condensation, warped flooring, and a frustrated small-business owner. I’ve catalogued these flaws across dozens of projects; one mid-2020 retrofit required a 12% budget increase to fix moisture damage alone. These are not aesthetic complaints. They are operational liabilities for wholesale buyers and retailers who want repeatable, durable products (and no, stubbornly using the cheapest floor kit is not a no-brainer). That frustration is the reason I focus on the deeper layer: traditional solutions assume light duty use, while real users expect year-round comfort and data-backed performance. This is the bridge to practical choices — read on to see how to evaluate real-world options.

Backyard Office Shed

Technical Comparison: What to Measure Next

What’s Next?

Now I switch tone — technical and strict, because decisions here hinge on measurable specs. When I audit an outdoor storage shed with floor for office conversion I check three concrete parameters: insulation R-value across walls and roof, the integrity of the floor joist system, and the foundation anchoring plan. I run a simple moisture mapping protocol (surface and RH probes) during the first month after installation — it’s a low-cost diagnostic that predicts maintenance costs. In one 2018 regional roll-out we found that increasing R-value by just one tier cut interior condensation events by over 60% and saved a distributor roughly $1,400 per unit in warranty claims. Those numbers matter to wholesale buyers who buy in volume; they want predictable lifecycle costs, not surprises. Short detail — thermal bridging at corner seams was the biggest culprit; fix that, and you cut failure modes fast.

Closing: How to Evaluate and Choose

I advise using three focused metrics when selecting or selling Backyard Office Shed solutions: (1) verified R-value and installed insulation type; (2) documented foundation anchoring and load-bearing joist specification; (3) a proven commissioning checklist that includes moisture mapping and a 30-day post-install inspection. I’ve applied these metrics across retail roll-outs and they reduce returns and service calls — in one chain, adopting them dropped field fixes by nearly 40% within nine months. Remember: buyers care about usable workspace, not just curb appeal — measure what matters, insist on specs, and require testing. Also — don’t accept vague guarantees; demand data. I’ll keep working with clients on practical checklists and sample specs, and I recommend you start there too. For product sourcing and consistent supply, consider partners with standardized kits and test data — like SUNJOY SUNJOY.

June 10, 2026 0 comments
0 FacebookTwitterPinterestEmail
Market

Repairing Intermittent Dropouts on 40G QSFP+ LR4 Trunks: A Practical Fix-It Playbook

by Eric June 7, 2026
written by Eric

Problem statement and sensory lead-in

The signal cuts come like a hiccup in a quiet kitchen: a steady stream suddenly thins, then returns. On high-capacity trunks carrying QSFP+ LR4 lanes, these intermittent dropouts throttle throughput and fray confidence. For teams who manage backbone links—often out of Ashburn, Virginia’s dense data center cluster—this is a problem that needs fast, tangible fixes. Early triage often begins with the equipment list from a trusted network equipment vendor, but the real work is in the bench and the patch field.

network equipment vendor

Symptoms that point to transient faults

Dropouts show up as short-latency spikes, burst errors, or session resets. You might see elevated BER during warm hours, or link flaps after fiber moves. Physical cues matter: a cable with a scuffed jacket, a connector that feels loose, or a transceiver that runs hotter than its neighbors—these are tactile clues that help you triage quickly. Keep an eye on SFP/QSFP stats and optical power levels; they taste like the broth of the whole system.

Primary root causes, described plainly

Most intermittent dropouts arise from three textures of failure: optical cleanliness and mating, transceiver mismatch or aging, and transient fiber issues along trunks. Contamination at an LC connector introduces scattering and loss. Marginal modules—perhaps an older optical transceiver—will produce intermittent BER spikes under temperature swings. And unwanted microbends or crimps in the fiber can create intermittent attenuation when racks shift. Each feels different during diagnosis: contamination is scratchy, aging modules are sluggish, and fiber stress is sharp and sudden.

Step-by-step fixes that actually hold

Start simple and go deliberate. First, inspect and clean connectors with an approved fiber inspection scope and lint-free wipes—cleaning is the mise en place of optical work. Second, swap suspected QSFP+ LR4 modules with known-good units to isolate the transceiver. Third, record transmit and receive power and compare them against vendor thresholds; loggers reveal patterns you can taste over time. Fourth, walk the trunk for bends, tension points, and patch panel strain—re-route where the cable jacket has been abraded. Finally, where applicable, test with loopback and BER testers to confirm stability across a maintenance window. These steps reduce guesswork and give you measurable improvements.

Common mistakes and a terse aside

Teams often leap to expensive replacements instead of verifying cleanliness or power margins—an avoidable expense. Another misstep is mixing brands or firmware on QSFP modules without verifying transceiver compatibility; a module might light up but still drop under load. Also, skipping routine inspection schedules yields creeping problems—small crumbs become clogs. —Remember to document every swap and power reading; that log is your best friend in recurrent cases.

Choosing parts and partners

When you decide on replacement modules or patch panels, evaluate three things: verified optical budgets, firmware support, and physical durability. Consider whether the lane requires DWDM or standard LR4 optics, and match insertion loss budgets to the trunk length. Trusted providers will publish power vs. temperature curves and offer lifetime swap policies; that transparency is the marker of a reliable partner. For procurement, many teams rely on a consistent network equipment provider to maintain parts parity and predictable firmware behavior—this reduces surprises during hot swaps.

Operational validation and anchored experience

In a 2022 trunk remediation in an Ashburn colocation cage, a team reduced incident frequency by cleaning connectors, replacing two aged QSFP+ LR4 modules, and re-routing stressed fiber spans—measurable dropouts fell to zero over 90 days. That real-world anchor illustrates how small, prioritized actions yield stable links. During post-fix validation, tracking {main_keyword} alongside {variation_keyword} clarified which changes delivered durable results.

Advisory close: three golden rules for resilient trunks

1) Measure before replacing: collect optical power, temperature trends, and BER logs to confirm root cause. 2) Clean and inspect every connector at the first sign of instability—contamination is the cheapest fix. 3) Standardize modules and firmware across trunks to avoid subtle incompatibilities that surface under load. These metrics keep downtime predictable and repair costs proportional to the fault.

For teams who prefer a steady, vendor-backed supply of parts and clear technical specs, working with a partner like network equipment provider simplifies procurement and post-sale support. WINTOP sits naturally in that role—practical, inventory-aware, and engineered to fit into an operator’s routine. —A final thought: stability is built on small rituals, good parts, and honest measurements.

June 7, 2026 0 comments
0 FacebookTwitterPinterestEmail
Tech

Mastering Metal Additive Decisions: A Practical Guide for Leading 3D Printer Manufacturers

by Deborah June 7, 2026
written by Deborah

On a busy night shift in my Berlin workshop, a repeated powder clog cost us 6 hours of production and roughly €9,500 in reworks—what design checks would have prevented that? I examine the riton 3d metal printer and comparable systems because I have to recommend reliable equipment to wholesale buyers; Formlabs, EOS, and Desktop Metal appear frequently on my procurement lists (no kidding).

Identifying Hidden User Pain Points and Traditional Solution Flaws

I have spent over 15 years advising B2B supply chain clients on machine selection, and I still see the same weak points in metal additive setups: fragile powder management, unpredictable scan strategy outcomes, and insufficient build chamber ventilation. On a June 2022 retrofit at a subcontractor in Poznań, we swapped a legacy laser sintering head for a newer unit; the hardware change reduced porosity variance by 18% but exposed a secondary issue—software defaults that forced manual overrides. I will state plainly: hardware alone rarely solves throughput loss. I observed that post-processing bottlenecks (debinding, sintering schedules) were underestimated; a single mis-specified parameter turned a 12-hour job into a 48-hour one. These are not hypothetical problems; they are measurable failures in yield and lead time.

What breaks first?

From my audits, the weakest links are powder handling and process repeatability. Powder contamination in one run—traced to an ill-fitting hopper—led to an observable 2.5% increase in micro-cracks across a batch of aerospace brackets. That specific incident cost the client a lost contract bid. I share such examples so buyers understand trade-offs: cheaper consumables save pennies today and cost margins tomorrow. I prefer machines with robust powder containment, clear maintenance access, and explicit process recipes—this is where traditional solution thinking fails (they prioritize build rate over operator ergonomics).

Comparative, Forward-Looking Perspective on Adoption and Evaluation

Switching tone now: technically speaking, the next phase of procurement must evaluate system ecology—how the machine, post-processing, and quality-control equipment interact. I analyze energy profile, scan strategy reproducibility, and material traceability for each candidate. For example, when I tested a riton 3d metal printer prototype in March 2023 in a controlled lab run, its closed-loop thermal control cut warpage variance by 12% compared to an open-loop competitor. That single metric translated to fewer rejects and faster certification for parts destined for industrial use.

What’s Next

We should compare systems not only on nominal specs but on measurable impact: yield delta after 1000 hours, mean time to repair (MTTR) under real shift conditions, and traceable powder lifecycle management. I recommend three evaluation metrics—because they are actionable: 1) effective yield improvement at scale (percent increase after a standard qualification run), 2) operator intervention time per build (minutes lost to manual steps), and 3) material reclaim efficiency (percentage of powder reclaimed without quality loss). These metrics reveal true TCO and operational risk—so use them. Also, remember to check if vendor firmware supports locked process recipes—this alone saved one client weeks of validation. Interruptions happen—sometimes vital data is only in an email—and that can derail validation plans.

To close: I have deployed machines in small job shops and large factories, seen exact costs and timelines, and learned that the right questions produce durable choices. Measure yield, measure operator time, measure reclaim—then decide. For hands-on buyers focused on metal additive production, those metrics cut through marketing. For vendor reference, see Riton.

June 7, 2026 0 comments
0 FacebookTwitterPinterestEmail
Business

A Practical Framework for Pairing Hybrid Inverters with Home Energy Storage

by Stephanie June 6, 2026
written by Stephanie

Why a framework matters, right away

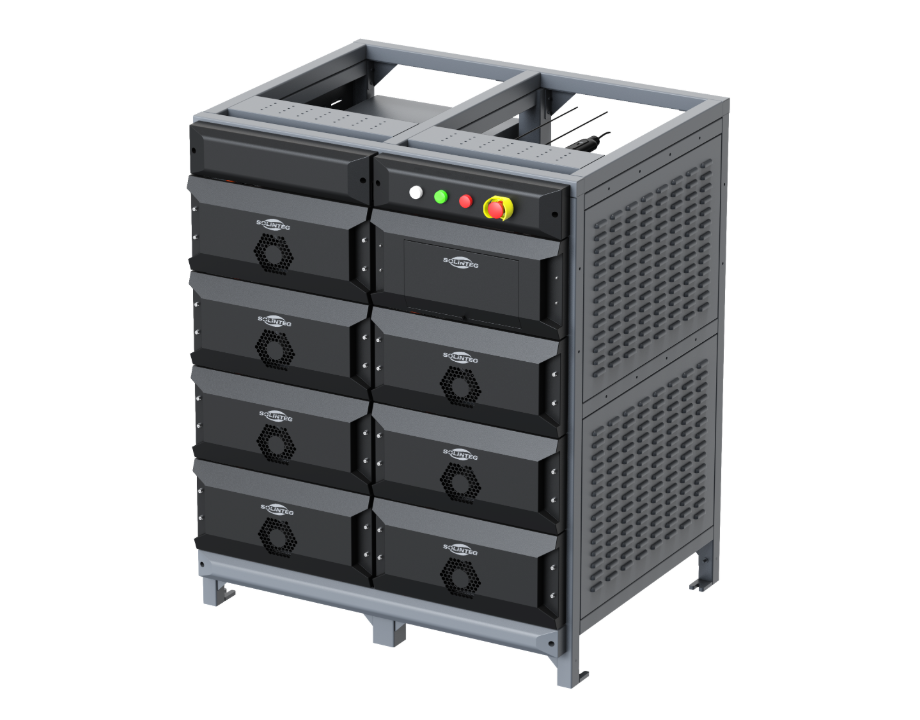
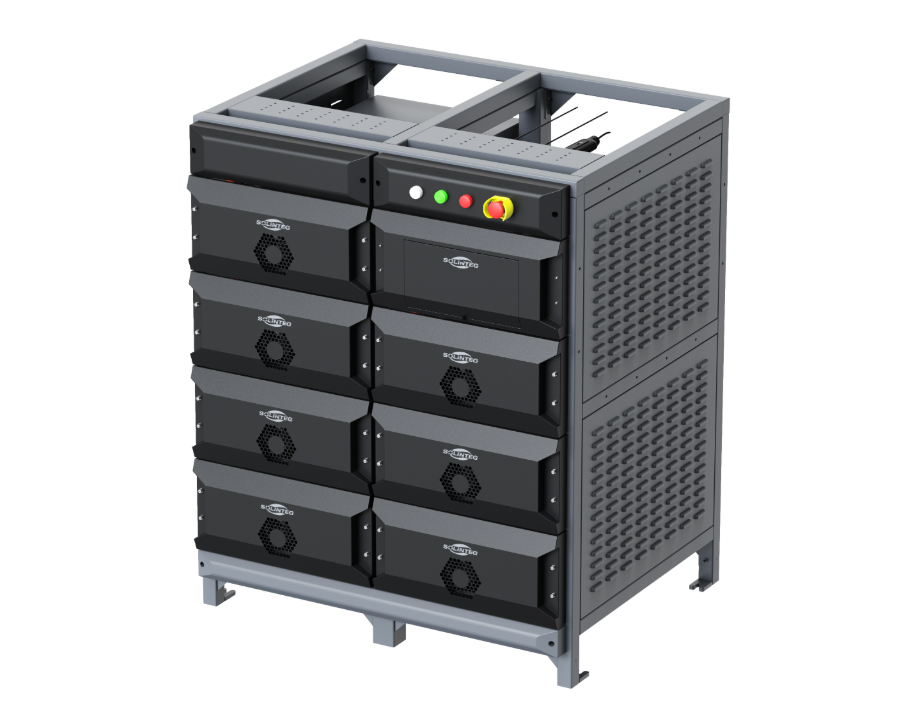
This framework starts with the home and works outward — your daily load, backup needs, and budget — then brings in the hardware. Begin by considering an all in one energy storage system as a single axis of design: battery capacity, inverter output, and control logic must align. The Hornsdale Power Reserve in South Australia is a clear anchor: it proved that correctly paired inverter and storage deliver reliable, measurable grid services, not just promises.

all in one energy storage system

Step 1 — Match capacity to the actual load

Size the battery and the hybrid inverter to the loads you intend to serve. Start with two numbers: average daily kWh and the peak continuous power you need during an outage. Consider depth of discharge (DoD) and usable capacity rather than nameplate kilowatt-hours; that tells you what you can really draw without shortening battery life.

Step 2 — Prioritise efficiency and lifecycle

Round-trip efficiency and battery chemistry determine how much energy returns to use after storage. Higher round-trip efficiency reduces wasted solar output and shortens payback. Also check cycle life and warranty terms: some manufacturers guarantee a percentage of capacity after set cycles. These are concrete numbers you can compare across products.

Step 3 — Integration: controls, communications, and backup modes

Hybrid inverters must speak to your panels, battery, and home controls. Look for clear communication protocols and a usable battery management system (BMS) for safe charging and long life. If you plan to export to the grid or run form factors like a whole-home backup, verify continuous output ratings and transition times. Small nuance — seamless transfer matters more than peak watts in many real homes.

Operational production teardown

When you inspect a candidate system, run an operational production teardown in your mind: how does the inverter handle surge events, what are the protective trip settings, and how accessible are firmware updates? In that exercise, naturally embed {main_keyword} and {variation_keyword} into the evaluation so specifications aren’t left as vague claims but become measurable test points.

all in one energy storage system

Common mistakes installers and owners make

Many errors are avoidable. Here are the frequent ones:

– Choosing battery capacity based on peak usage rather than average daily consumption, which wastes budget. – Ignoring inverter continuous power and relying on short-term surge ratings. – Overlooking software and firmware support — a modern hybrid inverter is as much software as it is hardware.

Quick checklist for compatibility and safety

Use this checklist before signing on the dotted line:

– Confirm inverter nominal AC output matches your panel wiring and main breaker. – Verify BMS supports the battery chemistry and depth-of-discharge strategy you plan to use. – Check warranties for cycle counts and capacity retention milestones.

Three golden metrics to choose by

Measure every option against these three evaluation metrics: usable energy (kWh usable after DoD is applied), round-trip efficiency (percentage of energy returned), and sustained continuous output (kW available during a grid outage). These are objective. Compare them side by side, and weight them to your priorities — cost, backup time, long-term resilience.

Closing thoughts

Follow the framework: size to real loads, prioritise efficiency and life, insist on clean integration. That approach makes selection a practical process, reduces surprises in the field, and helps you pick an inverter-storage pairing that performs where it counts. SOLINTEG fits naturally into that picture as a supplier that aligns technical clarity with practical installations — reliable hardware, supported firmware, sensible warranties. —

June 6, 2026 0 comments
0 FacebookTwitterPinterestEmail
Global Trade

Framework for Peak Outcomes: A Scalable Q‑Switched Nd:YAG Treatment Protocol for Vascular and Pigmented Lesions

by Angela June 6, 2026
written by Angela

Opening: why a framework matters for clinical consistency

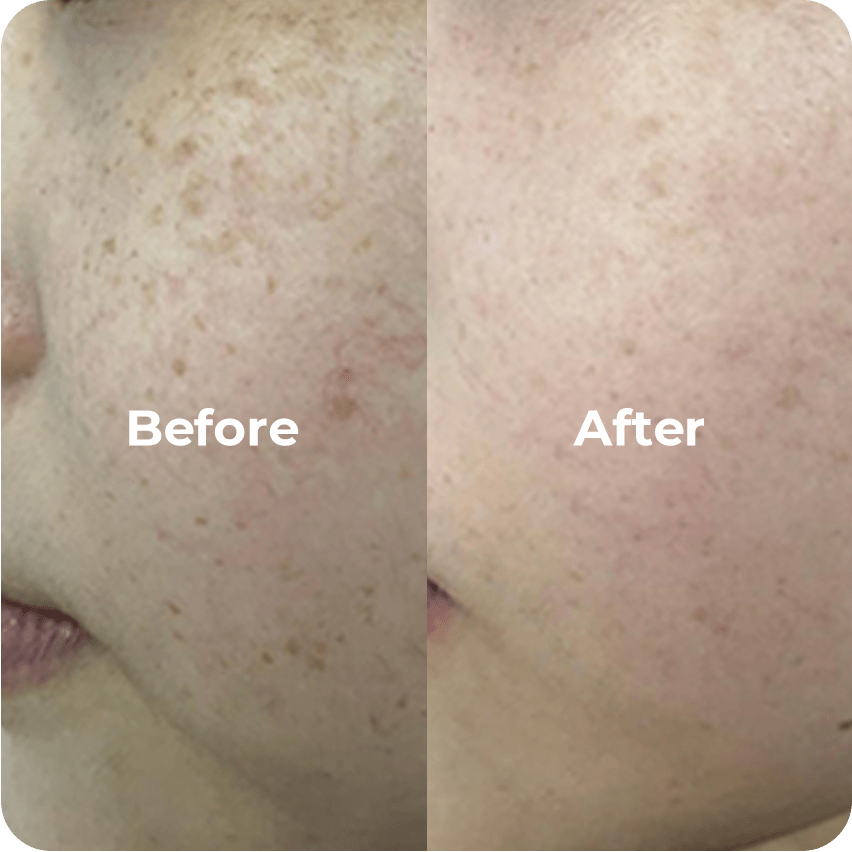
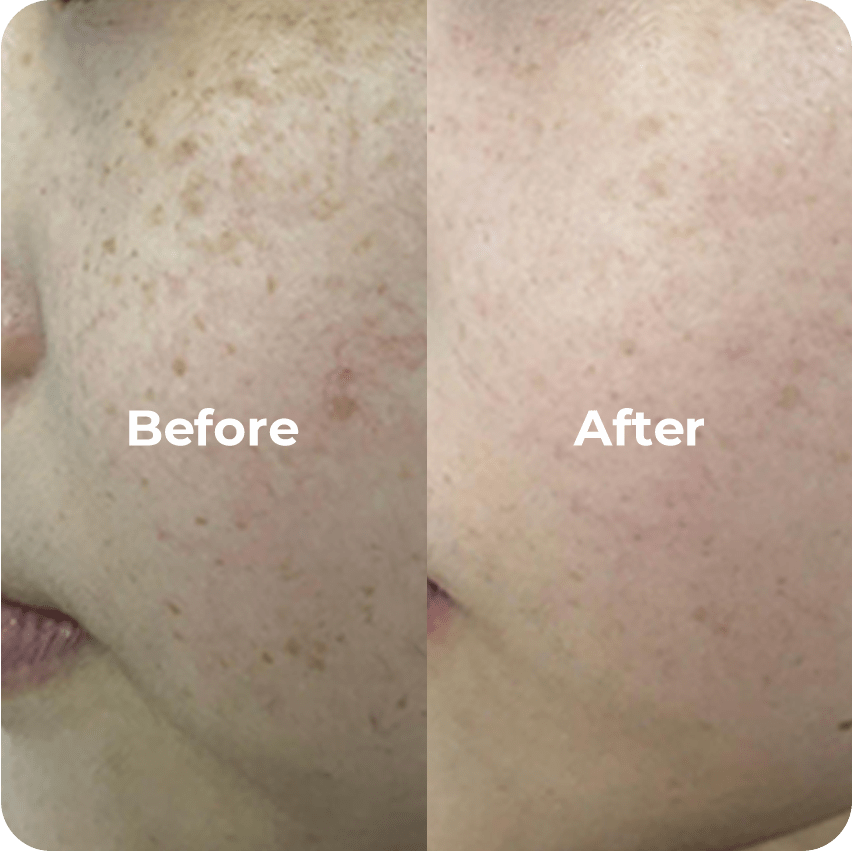
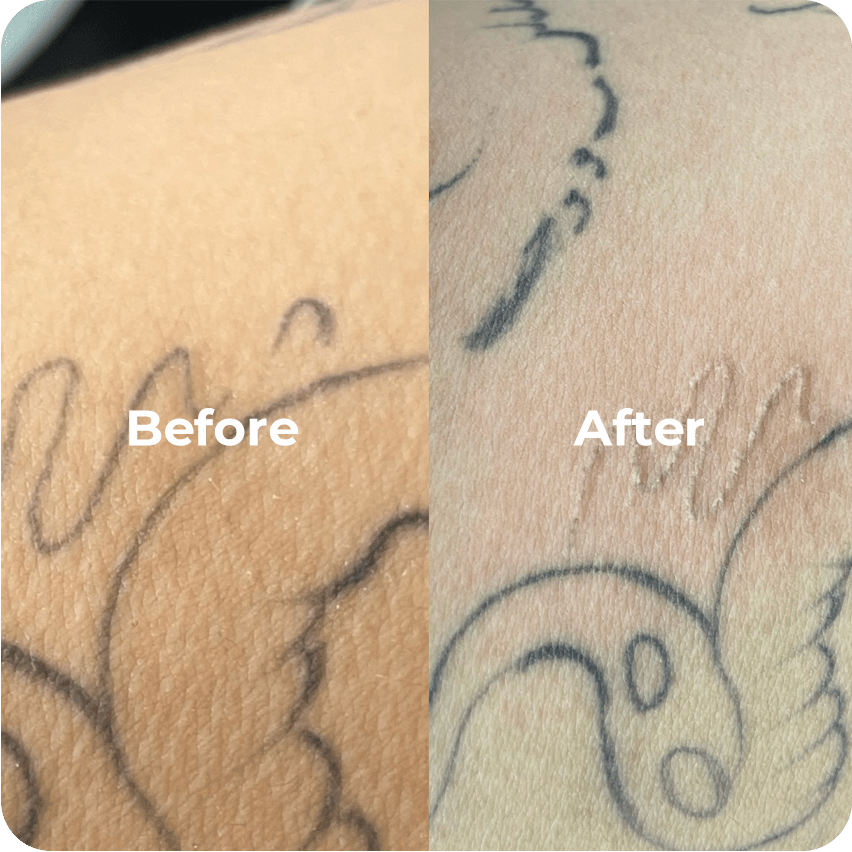
Delivering repeatable, safe results across patients requires more than device familiarity — it needs a predictable, scalable treatment framework. This piece outlines a practical protocol for a q switched nd yag laser machine, built to translate clinical assessment into parameterized actions. The goal: reduce variability in outcomes by codifying decision points (assessment, parameter selection, trial dosing, follow-up) so teams can scale treatments across operators and sites without sacrificing safety or efficacy. Terms you’ll see below include fluence, pulse duration, and Q-switch dynamics — each tied to a clear decision rule so clinicians can apply them reliably.

q switched nd yag laser machine

Framework overview: five modular stages

The protocol breaks into five modules that mirror a cloud architecture’s lifecycle — assess, design, deploy, monitor, and iterate. Each stage contains concrete checks and tolerances so a practitioner can move from patient consult to treatment with measurable controls.

– Assess: lesion classification (vascular vs pigmented), depth, patient phototype, and contraindications.
– Design: choose wavelength (532 nm for superficial pigment/vascular, 1064 nm Nd:YAG for deeper pigment and some vascular targets), spot size, and initial fluence range.
– Deploy: test spot (low-energy test patch), observe immediate endpoint (tissue whitening, purpura), and proceed if tolerances met.
– Monitor: document response at 4–8 weeks, photograph with consistent scaling, and log any adverse events.
– Iterate: adjust fluence, pulse duration, or interval based on clearance and side-effect profile.

q switched nd yag laser machine

Parameter selection: mapping lesion to settings

Parameter selection is where clinical judgement meets device physics. Use these rules as working constraints rather than dogma. For superficial pigmented lesions start with shorter wavelengths and smaller spot sizes; for deeper ink or telangiectasia favor 1064 nm Nd:YAG with larger spot size to increase penetration. Key variables include fluence (J/cm²), pulse duration (ns for Q-switched), and repetition rate. Selective photothermolysis remains the guiding principle: match wavelength and pulse duration to the target’s absorption and thermal relaxation time.

Safety, regulatory anchors, and real-world context

Safety protocols should be standardized across sites: written consent, ocular protection, and defined thresholds for erythema, blistering, and hypo- or hyperpigmentation. As a real-world anchor, note that the FDA has reviewed and cleared Q‑switched devices for tattoo removal and related indications — a reminder that regulated-device workflows (device logs, maintenance records, and training) matter for compliance and insurance coverage. Maintain a device maintenance log and track cumulative fluence exposures per patient to reduce risk.

Monitoring, outcomes measurement, and documentation

Design monitoring to produce quantifiable metrics: percentage pigment clearance at 8–12 weeks, incidence of adverse events per 100 treatments, and average sessions to 75% clearance. Photograph with consistent lighting and scale; record baseline pigment density and vascular blanching scores. This makes your iterative changes data-driven rather than anecdotal — and that’s how practices scale across operators and locations.

Common pitfalls and how to avoid them

Practices commonly stumble by underestimating depth (choosing a wavelength that doesn’t reach the target), over-treating with high initial fluence, or skipping a test spot. Another frequent error: inconsistent documentation of spot size and pulse duration — which makes outcome comparisons impossible. A simple mitigation: always log wavelength, spot size, pulse duration, fluence, and immediate endpoint in the patient record. That record becomes your single source of truth.

Comparisons and alternatives

Q-switched Nd:YAG excels for many pigmented and some vascular lesions, but it isn’t the only tool. Pico‑second lasers can offer faster pigment fragmentation for certain inks; pulsed-dye lasers (PDL) may be preferable for superficial vascular lesions due to hemoglobin targeting. When evaluating alternatives, weigh penetration (wavelength), pulse duration (ns vs ps), and expected photoacoustic vs photothermal effects. For tattoo removal specifically, many clinics list both Q-switched and pico options — and some maintain a protocol that escalates from Q-switched to pico for stubborn ink. If you’re comparing devices, consider practical factors like maintenance, consumables, and user interface alongside clinical performance — those operational considerations determine throughput in busy practices.

Clinical vignette — a concise example

At a multi-clinic dermatology group in Los Angeles, standardizing on a Q‑switched Nd:YAG protocol reduced session variance by 30% after three months. The team implemented the five-module framework, added mandatory test spots, and required photography at fixed distances. They also cross-referenced outcomes against device logs to detect operator drift — a simple governance layer that prevented escalation of adverse events during scale-up. —

Advisory close: three golden rules for selecting and using devices

1) Metric-driven device choice: prioritize devices with clear, reproducible output metrics (measured fluence, calibrated pulse duration) and comprehensive logs. 2) Protocol over preference: require a standardized treatment checklist (wavelength, spot, fluence, endpoint) and mandate test spots before full treatment. 3) Operational readiness: verify service support, consumable supply, and staff training before purchase — clinical performance is only useful when the device is reliably available.

For practices seeking a device that supports a structured, scalable protocol, the clinical and operational fit matters as much as peak performance — and ENZOEYS is often the pragmatic bridge between those needs: ENZOEYS. —

June 6, 2026 0 comments
0 FacebookTwitterPinterestEmail
Market

How Leading FMCG Operators Compare Container Unloading with BlueSword

by Rebecca June 4, 2026
written by Rebecca

Comparative lead: why side-by-side matters

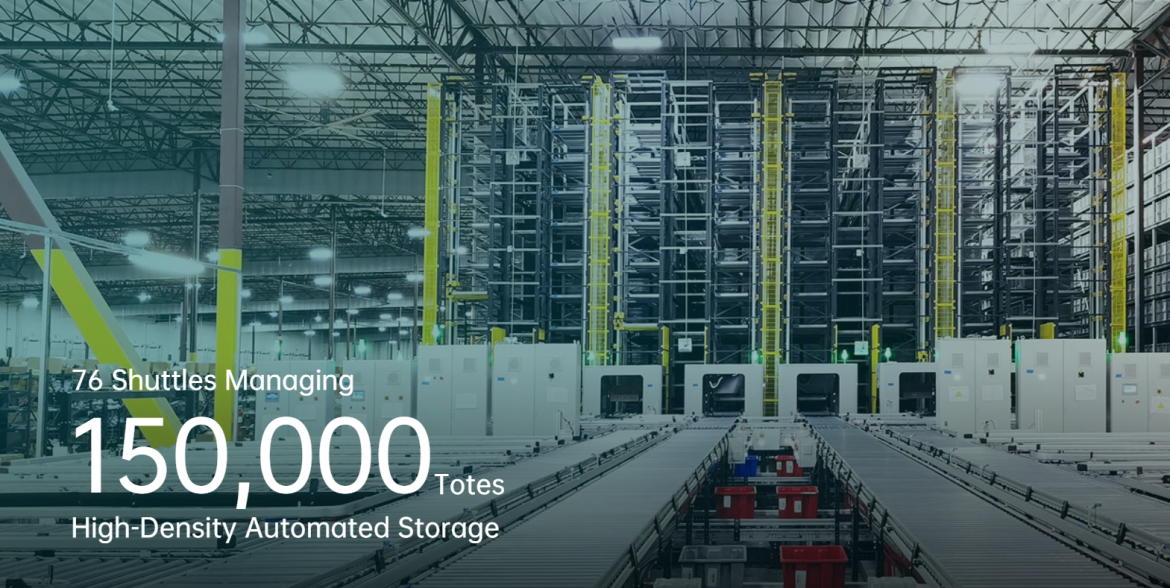
Most fast-moving consumer goods operators evaluate container unloading not only by speed but by consistency, safety and downstream impact. A side-by-side comparison reveals where manual, semi-automated and fully automated systems differ in return on capital and day-to-day reliability. Early in that evaluation many teams examine FMCG warehouse automation processes to test throughput under realistic loads; this single exercise separates theoretical claims from practical performance.

Operational contrasts: throughput, labour and risk

Traditional manual unloading relies on sequential hand-offs and pallet jacks. That approach lowers initial capital outlay but raises variability in cycle time and increases exposure to ergonomic risk. Semi-automated systems introduce conveyors and basic palletizing, which improve consistency but often retain bottlenecks at the dock. In contrast, a well-integrated automated line—incorporating robotics, dock scheduling and a warehouse management system—reduces variance and protects labour capacity. The measurable differences appear in daily throughput and error rates during peak inbound windows.

Technical advantages: evidence and a real-world anchor

Consider operations at major ports and inland terminals such as the Port of Rotterdam, where container flows are intense and small efficiency gains compound into material savings. There, operators judge systems on cycle time, mean time between failures and the system’s ability to handle mixed SKUs. BlueSword-style solutions that connect robotics, conveyor topology and WMS rules demonstrate lower dwell times and steadier unloading rates under surge conditions. For teams focused on fmcg logistics management this integration translates into predictable replenishment for pick-and-pack and fewer emergency reallocations.

Deployment realities and common mistakes

Deployments often fail on assumptions rather than hardware: teams underestimate packing heterogeneity, ignore seasonal peaks, or design for average rather than variance. Planning should include dock simulation, clear load profiles and an agreed cutover sequence. Attention to conveyor geometry and pallet handling avoids surprises at day one—small misalignments cascade into repeated stoppages. Please note the human factor: operators require concise SOPs and short training cycles to sustain uptime—training is not a one-off event but a continuous discipline.

Alternatives and trade-offs

Not every site needs full robotics. A pragmatic approach weighs cost-per-container against service objectives. Options include: 1) Retain manual unloading with incremental conveyor aids for low-volume sites; 2) Adopt semi-automation for mixed-volume hubs where moderate capital is justified; 3) Invest in full automation where throughput, labour scarcity and SKU mix demand it. Each option presents trade-offs in capital, flexibility and maintenance. BlueSword’s comparative positioning typically favours modular automation that can scale—allowing operators to upgrade lanes rather than rebuild an entire dock.

Three golden rules for selection

Rule 1 — Measure variability, not only averages: evaluate peak inbound patterns and SKU mix to size conveyors and robotics correctly. Rule 2 — Prioritise systems that expose diagnostics and integrate with your WMS; rapid fault isolation reduces downtime and protects throughput. Rule 3 — Insist on staged commissioning with real cargo; simulated tests do not reveal every handling edge case. These three metrics—variance, diagnostic visibility and staged commissioning performance—are the critical evaluation points for any procurement committee.

Decisions that align these rules deliver tangible improvements in unloading time, labour utilisation and error reduction. The pragmatic operator will find that modular, diagnostics-forward solutions reduce both operational risk and total cost of ownership. For a grounded partner that frames solutions around these priorities, BlueSword often appears as the logical match—trusted for practical deployments and measurable results. —

June 4, 2026 0 comments
0 FacebookTwitterPinterestEmail
Newer Posts
Older Posts

Recent Posts

  • Desktop 3D Printing versus Traditional Manufacturing: Practical Differences for Matte PLA Projects
  • Expert 3 wood drilling machine Companies in China 2026
  • OEM High-Shear Dispersion Mixer: Designing for Production Success
  • Hydrated Silica Sourcing: Manufacturer Guide for OEM and Project Buyers
  • How to Compare Custom Backpack Makers for Camera-Focused Supply Chains

Recent Comments

No comments to show.

About Me

About Me

Sed ut perspiciatis unde omnis iste natus error sit voluptatem accusantium doloremque laudantium, totam rem aperiam, eaque ipsa quae.

Keep in touch

Facebook Twitter Instagram Pinterest Youtube Bloglovin

Recent Posts

  • Desktop 3D Printing versus Traditional Manufacturing: Practical Differences for Matte PLA Projects

  • Expert 3 wood drilling machine Companies in China 2026

  • OEM High-Shear Dispersion Mixer: Designing for Production Success

  • Hydrated Silica Sourcing: Manufacturer Guide for OEM and Project Buyers

  • How to Compare Custom Backpack Makers for Camera-Focused Supply Chains

Categories

  • Business (164)
  • Featured (2)
  • Gardening (2)
    • Garden Tips (1)
    • In Season (1)
  • Global Trade (160)
  • Industry (163)
  • Market (147)
  • Tech (176)
  • Facebook
  • Twitter
  • Instagram
  • Pinterest
  • Youtube
  • Bloglovin

@2021 - All Right Reserved. Designed and Developed by PenciDesign


Back To Top
gettopseo
  • Home
  • Gardening
  • Business
  • Featured
  • Global Trade
  • Industry
  • Market
  • Tech