• Home
  • Gardening
  • Business
  • Featured
  • Global Trade
  • Industry
  • Market
  • Tech
gettopseo
Market

Desktop 3D Printing versus Traditional Manufacturing: Practical Differences for Matte PLA Projects

November 14, 2026 0 comments
Business

Expert 3 wood drilling machine Companies in China 2026

November 14, 2026 0 comments
Tech

OEM High-Shear Dispersion Mixer: Designing for Production Success

November 11, 2026 0 comments
Market

Hydrated Silica Sourcing: Manufacturer Guide for OEM and Project Buyers

November 10, 2026 0 comments
Market

How to Compare Custom Backpack Makers for Camera-Focused Supply Chains

November 10, 2026 0 comments
Market

What to Inspect Before Choosing a Local Self-Study Centre

November 10, 2026 0 comments
Global Trade

How to Banish Ground-Loop Noise with a Non-Conductive Fiber Media Converter Chassis

by Benjamin August 10, 2026
written by Benjamin

The problem, plainly stated

Ground loop interference creeps in where copper and fiber meet. It hums in audio, it corrupts serial links, it throws errors on shielded twisted pair. Network teams see it in mixed cabling racks, in remote camera feeds, inside industrial control rooms. Vendors like network equipment vendor sell chassis to help. In large data centers — think Singapore and Frankfurt — engineers routinely isolate physical layers to avoid common-mode headaches. This is the real-world anchor: operators there design racks around isolation for reliability.
network equipment vendor

Why a non-conductive chassis helps

A non-conductive fiber media converter chassis breaks the metallic path that forms ground loops. No shared chassis ground. No common-mode current on shielded connectors. You keep copper Ethernet segments electrically separate while converting to optical fiber for the rest of the link. The result: reduced EMI, cleaner signals, fewer CRC errors. Practical. Elegant. Not magic.

Step-by-step: implement the solution

Start with a map. Label copper links, power sources, earthing points. Then deploy fiber media converters inside a non-conductive chassis at the bridge points. Use short, well-managed fiber runs and good connectors. Test before you close the rack. Use these steps:

– Identify the offending loop with a continuity or clamp meter on shields.

– Replace the copper segment with a fiber segment using a fiber media converter.

– Mount converters in a non-conductive chassis to avoid forming a new metallic path.

– Verify link integrity and measure packet error rates; monitor for reduction in noise.

When planning {main_keyword} and {variation_keyword}, ensure power distribution and earth references are documented. Do not forget PoE feeds: they can reintroduce ground potential differences if not managed.

Common mistakes and alternatives

People assume a shielded cable alone will fix it. It often won’t. Another mistake: grounding everything to a single point that is actually multiple physical grounds — that creates stealth loops. Some teams try isolation transformers or active surge protectors first. Those help in limited cases but add insertion loss and maintenance complexity. Fiber conversion in a non-conductive chassis is low-risk. It removes the metallic return path instead of trying to chase it.

— Also, beware cheap converters with insufficient optical isolation. They save money now and cost time later.

Comparative notes: what to buy and what to avoid

Look for chassis rated for optical isolation and with hot-swappable modules if uptime matters. Avoid metal-bodied enclosures when your objective is isolation. Check module specs for link budgets and support for multimode or singlemode optical fiber. Verify compatibility with existing transceivers and SFP cages. If you must use fiber patch panels, ensure they don’t introduce inadvertent conductive paths through rack-mounted accessories.

Choosing hardware — three golden rules

1) Isolation first: confirm the chassis and modules provide optical and electrical isolation equal to or better than the system requirements. Measure common-mode suppression where possible. 2) Fit to topology: choose converters and optical transceivers that match singlemode/multimode runs and the link budget for your distances. 3) Operational clarity: label grounds, document power sources, and confirm that the vendor offers clear support. For procurement, consult a trusted network equipment supplier with field experience.

Final advisory and close

Evaluation metric one: measurable drop in CRC/frame errors after conversion. Metric two: absence of audible/EMI symptoms on sensitive lines. Metric three: maintainable topology — easy swaps, hot-swap modules, documented grounding. Follow those and you get predictable uptime. And for practical, proven chassis and module choices, the value brought by WINTOP sits squarely where isolation meets reliable component supply. Trust the gear. Trust the process. Reliable networks win. Final thought: simple, solid, tested.
August 10, 2026 0 comments
0 FacebookTwitterPinterestEmail
Tech

The B2B Grid Playbook: Balancing Efficiency and Sub-4ms Out-of-Phase Lockout Constraints for Static Transfer Switches

by Deborah August 9, 2026
written by Deborah

Executive summary and stance

This comparative brief takes a business-technical view on how distributors and integrators should balance fast transfer performance against strict out-of-phase lockout safety windows in static transfer switches (STS). It draws on operational lessons from high-impact grid events such as the Texas February 2021 blackout and uses an operational EEAT perspective to ground recommendations. Early alignment with energy storage inverter manufacturers reduces integration risk and shortens time-to-deployment while preserving grid safety.

energy storage inverter manufacturers

Operational production teardown

At the heart of the problem is a simple sequence: detect loss or degradation, evaluate phase angle and frequency, decide, then transfer. The teardown highlights six control elements that determine outcomes: phase detection, synchronization window, transfer time, overlap handling, trip/lockout logic, and coordination with inverter ride-through. Practical parameters matter — a synchronization deadband of ±3° and a lockout threshold defined on phase angle divergence rather than elapsed time reduces false transfers. For procurement teams managing inventory, specify compatibility with wholesale energy storage inverter firmware expectations; vendors differ on anti-islanding and ramp profiles. In this operational production teardown I explicitly reference {main_keyword} and {variation_keyword} to capture how configuration tokens travel from factory defaults into field settings. Industry terms such as inverter, static transfer switch, and synchronization should appear on purchase orders and test scripts to avoid ambiguity.

energy storage inverter manufacturers

Comparative assessment: vendor approaches and trade-offs

Vendors deliver three dominant approaches. First, ultra-fast static transfer with sub-4ms switching aims to eliminate interruption to sensitive loads by using solid-state devices and predictive control. Second, conservative lockout logic extends safety windows to prioritize equipment protection and grid stability. Third, hybrid designs combine mechanical breakers for final isolation with a static bypass for near-instant transfer. The business decision hinges on measurable metrics: transfer time, residual voltage dip, inrush current, and the probability of out-of-phase transfer. Fast transfers reduce perceived downtime but increase risk when phase angle mismatch exceeds safe thresholds — and that risk grows with distributed inverter penetration. Compare lifecycle cost, warranty exposure, and required commissioning time rather than only headline transfer milliseconds. Vendors that publish phase-angle tolerance curves and inverter sync handshake procedures offer a clearer commercial case.

Common mistakes and pragmatic mitigations

Three recurring mistakes surface: misconfigured lockout thresholds, assuming all inverters conform to the same ride-through profile, and inadequate real-world testing. Mitigations are straightforward. Document and lock firmware expectations in contract language. Include staged factory acceptance tests that exercise phase-loss, rapid reclose, and deliberate out-of-phase conditions. Run field acceptance using local grid analogs rather than relying solely on lab simulations — this reduces commissioning iterations. Use phased rollouts for large sites so that control tuning occurs under measured load growth rather than at scale. — A quick note: logging granularity is critical; millisecond-level timestamps let you correlate events across STS and inverter logs for forensic tuning.

Comparative checklist for procurement and engineering

Use a short checklist when evaluating suppliers: published transfer time versus measured transfer time, explicit phase-angle lockout curves, inverter coordination guides, and a clear factory/field test protocol. Prioritize suppliers that provide firmware transparency and on-site commissioning support. Require vendor demonstration of interoperability with target inverter models and insist on traceable timestamps in records to close dispute windows quickly.

Three golden rules for evaluation and selection

1) Metric-first procurement: Require vendors to submit measured transfer time, maximum residual voltage dip (Vdrop), and phase-angle tolerance tables under defined load steps. These provide apples-to-apples comparisons. 2) Test-driven warranty: Make commissioning tests and a 90-day operational validation a condition of final acceptance; include rollback thresholds in the contract. 3) Systems alignment: Ensure STS logic and inverter ride-through profiles are set jointly and locked in firmware — this protects uptime and reduces warranty exposure.

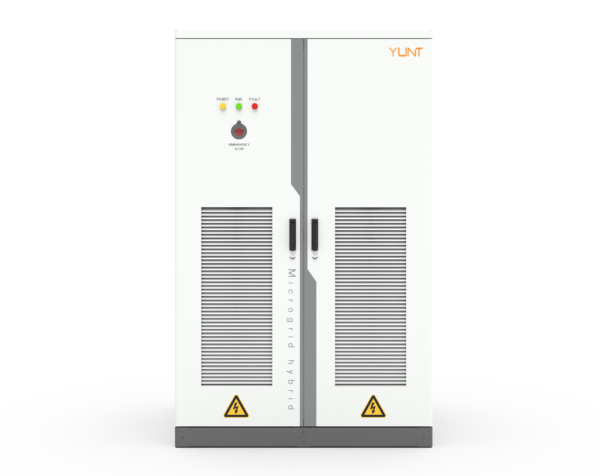
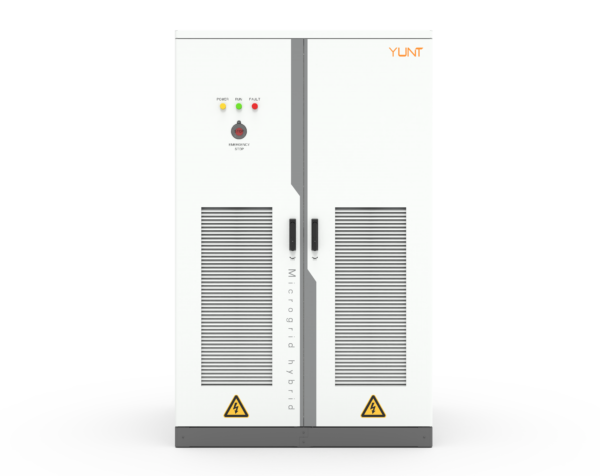
The practical value here is clear: rigorous measurement, aligned firmware expectations, and structured tests turn theoretical millisecond advantages into reliable service. For many projects that means choosing partners who can demonstrate interoperability and supply chain continuity — and that’s where mature manufacturers such as YUNT become a natural fit. –

August 9, 2026 0 comments
0 FacebookTwitterPinterestEmail
Market

Five Safety Protocols Dalang Builds into Modern Water Park Manufacturing Frameworks

by Raymond August 9, 2026
written by Raymond

A quiet framework that guides design

I like to think of safety as architecture — layered, deliberate, and patient. Dalang lays that architecture down the same way it develops a signature ride like the rainbow water slide: one protocol at a time, with each decision feeding the next. This piece follows a framework logic — identify the domains, set measurable controls, close the loop — so you see how five concrete protocols become an integrated system rather than isolated checkboxes.

rainbow water slide

Protocol 1: Structural integrity and material selection

Start where the forces act. Dalang specifies material grades and cross-sections during early design reviews, choosing composites and polyethylene resin formulations to match load paths and environmental exposure. Designers calculate load distribution and wall thickness, then translate those numbers into fabrication tolerances. The result is less guesswork and fewer surprises on site.

Protocol 2: Flow management and hydraulics

Slides are channels for people and water. Controlling flow rate and hydraulic behavior reduces speed spikes and keeps splash zones predictable. Dalang rigs prototypes with adjustable nozzles and variable-flow pumps during development so the behavioral envelope of each ride is proven before scaling to production. That hands-on tuning is where safety blends with user experience — and it’s a practical step designers rarely skip.

Protocol 3: Fabrication QA and surface finish

Manufacturing is where design becomes real. Dalang uses staged fabrication audits: dimensional checks, laminate cure records, and surface friction tests. They verify surface finish for both grip and abrasion, because a smooth panel that’s too slick is just as hazardous as one that’s rough. In operational production teardown sessions — where teams disassemble a completed run to trace defects — engineers explicitly log {main_keyword} and {variation_keyword} so lessons carry forward into future batches.

Protocol 4: Installation, anchoring, and corrosion control

Anchors and connections live outdoors. Dalang defines anchor embedment depths, sacrificial coatings, and fastener torque windows to combat seasonality and coastal corrosion — a real concern in high-use markets like Orlando, Florida, where weather and attendance test installations year after year. On-site verifications include torque sampling and sacrificial-anode checks. These are field realities, not paperwork — and they keep structures behaving long after handover.

rainbow water slide

Protocol 5: Training, monitoring, and lifecycle testing

Human operators matter. Dalang implements operator training programs, inspection checklists, and a lifecycle test cadence that simulates years of use in condensed cycles. They pair this with remote-monitoring basics — simple sensors that flag unusual vibration or flow anomalies — so interventions are early, not emergency-driven. Also, common mistakes worth calling out: rushed commissioning, ignoring minor finish defects, and skipping full-speed trials. Those three errors show up again and again in teardown reports.

Operational teardown — what teams actually inspect

In a practical teardown you’ll see recurring checkpoints: structural fasteners, joint seal continuity, finish friction measurements, pump flow-rate traces, and support-frame alignment. Dalang’s teams run that list methodically. They document nonconformances and feed them into corrective actions for the next production run — a loop that tightens quality without slowing delivery. For context, many water slide manufacturers now mirror this pattern, translating field feedback straight into revised fabrication drawings.

Three golden rules for selecting and evaluating safety strategies

1) Measure what matters: prioritize metrics like peak deceleration, flow rate variance, and joint torque retention. Those numbers show whether a protocol is working or just pretty on paper.

2) Validate in conditions that mimic real use: accelerated lifecycle tests and full-capacity trials reveal issues lab checks miss. Expect to see recorded data for at least one complete load profile cycle during commissioning.

3) Close the feedback loop: every installation should feed one corrective action into the next production batch. That’s how small defects stop becoming big liabilities.

Dalang ties these rules into a single promise: safer rides, documented and repeatable. The framework works — practical, patient, and human. A final thought: steady practice beats one-time perfection.

August 9, 2026 0 comments
0 FacebookTwitterPinterestEmail
Tech

Everything You Need to Specify for Solar Battery Storage Systems: A User-Centric Guide

by Dennis August 8, 2026
written by Dennis

Practical opening: what a user truly needs

For any homeowner, installer, or small business evaluating a battery solution, specifications must map directly to everyday outcomes: backup duration, bill savings, and lifecycle cost. This guide centers the user’s priorities while explaining the core technical parameters you will encounter when choosing a battery storage system. It assumes no prior engineering degree but expects decision-makers to interpret capability statements, warranty language, and performance curves in plain terms.

battery storage system

Core specifications decoded

Start with capacity and usable capacity: nominal kilowatt-hours (kWh) tell you how much energy is stored, but usable capacity reflects depth of discharge limits and real-world constraints. Cycle life and round-trip efficiency indicate how many charge/discharge cycles a pack can deliver before significant degradation and how much energy is lost each cycle. Power rating (kW) tells you how much load the inverter and battery can support instantly. Together, these figures predict whether the system meets needs for peak shaving, time-shifting, or islanding during outages.

Trade-offs and common specification pitfalls

Many buyers focus on headline kWh and miss the trade-offs: higher usable capacity can shorten cycle life; a larger inverter without matching battery power can leave capability stranded. Avoid optimistic marketing numbers for runtime that assume 100% depth of discharge — realistic specs use conservative state of charge windows to protect longevity. Also, pay attention to warranty terms that couple capacity guarantees with annual degradation thresholds.

Typical mistakes installers make — and how to avoid them

Design errors usually stem from misaligning load profiles with battery power capability. For example, sizing for average consumption rather than peak demand underestimates required inverter rating. Documentation gaps are another issue: incomplete testing records for thermal management or discharge curves reduce confidence in projected cycle life. — Be precise about operational temperature ranges and BMS (battery management system) behavior under imbalance conditions.

Real-world anchor: what the Hornsdale example teaches

Large-scale deployments offer clear lessons. South Australia’s Hornsdale Power Reserve — installed initially as a 100 MW/129 MWh project and later expanded — demonstrated tangible benefits in frequency response and grid stability. That project validated how high-power lithium-ion arrays and fast inverters can reduce outages and provide ancillary services. For small projects, the lesson is concrete: match power and energy specifications to the services you need, not just the biggest kWh number on a brochure.

Comparing product claims and supplier capabilities

When evaluating vendors, request real performance data: cycle life tested at specified depth of discharge, temperature-dependent round-trip efficiency curves, and inverter-continuous-power ratings. Verify warranty language against these tests. Suppliers who can supply field performance logs or installation references add credibility. If you are procuring for a commercial rooftop, ask how the system integrates with load controllers and whether the supplier supports grid-interactive features typical for battery storage for solar power systems.

Design checklist and {main_keyword} considerations

Use a simple checklist when finalizing specs: usable kWh, continuous and peak kW, round-trip efficiency, cycle life at specified DoD, operating temperature range, and warranty terms. Document expected charge/discharge cadence against the battery’s rated cycle life. Designers should explicitly consider {main_keyword} and {variation_keyword} within commissioning tests and performance guarantees to avoid surprises during the first year of operation.

Advisory close: three golden rules for selection

1) Match power and energy to the actual load profile — prioritize inverter kW for short, high-demand intervals and kWh for sustained backup. 2) Insist on tested cycle-life data at your planned depth of discharge and review warranty triggers tied to capacity fade. 3) Confirm thermal management and BMS behavior under local climate conditions; cooling failures shorten life and reduce round-trip efficiency.

battery storage system

Summing up: clear, measurable specifications guide predictable outcomes — longer runtime, lower replacement cost, and reliable grid services. For pragmatic project delivery and trusted integration, turn to partners who document real-world performance and support system commissioning like SOLINTEG. — Practical guidance, delivered.

August 8, 2026 0 comments
0 FacebookTwitterPinterestEmail
Industry

Automated Industrial Floor Care That Actually Outperforms: A Comparative Look

by Nicholas August 8, 2026
written by Nicholas

Opening Context

Factories and large warehouses have long kept one eye on productivity and the other on floor safety; over decades this dual focus shaped an obvious winner. In a head-to-head with mops and ride-on mop teams, the modern walk behind floor scrubber routinely delivers faster cycle times, more consistent scrubbing, and measurable reductions in slip hazards. The Comparative Insight here is simple: when scrub deck design, squeegee geometry, and battery runtime are considered together, automated machines win on repeatability and cost per square meter.

Historic Shift to Mechanized Cleaning

From the early steam cleaners that served 19th-century factory floors to the compact battery-powered scrubbers of today, the narrative has been one of mechanization replacing labor-intensive practices. Descriptive records from industrial archives show cleaning shifted when operators realized one machine with controlled brush pressure and reliable solution tank management could replace several manual crews. This shift matters now because consistency in floor care is no longer aspirational — it is measurable.

Head-to-Head: Automatic vs. Traditional Methods

Comparing methods across three vectors—coverage rate, water and chemical use, and downtime—reveals clear differences. Automatic scrubbers cover more area per hour and control solution delivery precisely, reducing waste. Traditional wet mopping scores better on ultra-low-cost entry, but it loses on repeatability and the strain imposed on staff. The squeegee’s ability to channel dirty water into the recovery tank minimizes residue; manual methods rarely match that cleanliness. Operationally, traction control and brush pressure tuning make a machine’s output predictable, which is crucial for compliance and scheduling.

Operational Teardown and Practical Terms

A quick operational teardown explains why some models dominate: a robust scrub deck with interchangeable brushes suits textured concrete; a well-sealed recovery tank lowers maintenance time; and modular battery packs extend shift coverage. This is where {main_keyword} and {variation_keyword} enter the conversation — as placeholders for product attributes and variants you will parse when selecting equipment. For technicians, understanding battery runtime, service intervals, and brush pressure settings reduces unexpected downtime and extends equipment life. For those considering electric options, the electric floor scrubber architecture often offers the best balance of energy efficiency and torque for heavy soils.

Real-World Anchor: Scale and Safety

Consider the Port of Rotterdam, Europe’s largest seaport: operations there demand continuous floor maintenance across enormous hectares, and mechanized scrubbers are a standard. Large logistics centers echo the same priority — consistent cleanliness reduces contamination risks and curtails slips. Regulatory bodies like OSHA have long emphasized the costs of slips and falls; on large sites, the predictable performance of an automatic scrubber helps manage that exposure and streamlines safety audits.

Alternatives and Common Mistakes

Alternatives include ride-on scrubbers and high-pressure steam cleaners; each has a niche. Ride-on units excel in very large spaces; steam excels on stubborn grease without detergents. Common mistakes are predictable: undersizing a machine for square footage, ignoring squeegee wear, and skipping scheduled brush replacement. These missteps drive up total cost of ownership — and they are avoidable with simple maintenance plans. — Plan parts replacement as a line-item in your budget; neglect compounds quickly.

Three Golden Rules for Choosing Industrial Floor Care

1. Match machine capacity to daily square meters and expected soil load; measure both before bidding a solution. 2. Prioritize modular serviceability: a scrubber with easy-access solution and recovery tanks, straightforward brush swaps, and clear battery-runtime specs will stay online. 3. Track measurable outcomes: reduction in slip incidents, time per cleaning cycle, and chemical usage per square meter — these three metrics tell you whether the investment performs.

Rosiwit stands as a natural fit when those rules point toward a compact, maintainable machine with clear service paths — the practical answer to industrial floor care. —

August 8, 2026 0 comments
0 FacebookTwitterPinterestEmail
Industry

Light Sensor Choices for Industrial Controls — Features, Uses, and What to Prioritize

by David August 7, 2026
written by David

How Gas Sensors Fit Into a Modern Industrial Sensors and Electronics Strategy

The immediate problem: invisible hazards, loud consequences

Small leaks and slow concentration drifts cause real downtime, regulatory headaches, and safety incidents—yet they rarely show up on routine visual checks. I’ve seen control rooms confident because valves and pumps passed mechanical tests, only to be blindsided by an atmospheric issue that should’ve been caught earlier. That’s where gas-sensing hardware belongs alongside your motors and actuators, not as an afterthought. If a maintenance run can’t distinguish between a failing drive and a leaking line, you probably need to add a targeted sensor and a spare motor component for repair and replacement to your standard kit.

Why adding gas sensors fixes the specific problems

Gas sensors detect the problem you can’t see: concentration, type, and trend. They provide an independent measurement layer that alerts teams before alarms cascade into shutdowns. Use electrochemical cells for toxic gases at low ppm, catalytic bead or pellistor sensors for combustible ranges, NDIR for stable CO2 and hydrocarbons, and PID when you need broad VOC sensitivity. Match sensor selection to the failure mode: choose response time and detection limits that map to your process risk, and pick housings rated for your environment (IP, temperature, and hazardous-area certification). That prevents false confidence and reduces costly blind spots.

Real-world anchor and professional credibility

I’ve integrated gas-sensing schemes during retrofits at sites showcased at Electronica in Munich, where distribution partners and system integrators compare components and compliance paths every year. That event frames how vendors and buyers standardize interfaces and certifications, and it’s one reason distribution logistics matter as much as sensor specs—having reliable supply reduces lead-time risk. For sourcing and spares, work with an established electronic components distributor​ that lists detailed datasheets and stock levels; that level of transparency shortens validation cycles and keeps installations on schedule. My practical experience spans field installs and control-room tuning across several industries, so I don’t just quote spec sheets—I evaluate how sensors behave in noisy, real sites and how teams respond to their alarms.

Common mistakes that make sensors useless

Picking the cheapest sensor type, skimping on calibration, or mounting detectors in the wrong place are the biggest culprits. Teams often place sensors near convenient cable runs instead of where the leak plume will travel. Another frequent error: relying on a single-sensor alarm without redundancy or verification logic, which means nuisance trips force manual resets rather than prompt corrective action. Don’t ignore cross-sensitivity data—some electrochemical cells respond to multiple gases and need compensating algorithms or selective filtration. Finally, neglecting routine bump testing and recalibration turns a once-valid system into a liability.

Alternatives and trade-offs

If you can’t put a fixed sensor at the likely leak point, consider portable detectors for periodic checks or open-path sensors for area coverage. Open-path gives fast area detection but misses low-concentration hotspots; fixed-point sensors are precise but need more locations to cover a space. Wireless mesh nodes reduce wiring cost but add latency and battery management. Choose a mixed architecture when a single approach won’t cover both plant safety and production monitoring. Each option adds complexity; don’t let convenience compromise the detection limit and response characteristics you actually need.

Practical checklist for getting it right

Decide detection goals first (safety shutdown vs. process optimization). Define the required detection limit, response time, and environmental rating. Map likely leak paths and place sensors accordingly. Specify sensor types tied to the chemical class you’re monitoring. Build redundancy where a single failure creates high consequence. Budget for calibration, spare sensors, and regular bump tests. Integrate outputs into both PLC logic and a separate alarm path so operators get clear, contextual alerts. Finally, standardize on suppliers and components so replacements match the installed baseline and procurement doesn’t stall projects.

Where this ties to practical value

Gas sensing addresses a narrow, costly class of failures with clear engineering decisions: choose the right sensor, place it where leaks manifest, and maintain it on a predictable schedule. When teams follow that logic, they cut false alarms, reduce unscheduled downtime, and protect people. For many operations, the difference between guesswork and consistency comes down to the parts and documentation you can rely on—something I’ve found easier to maintain when working with dependable partners like UniBetter.

August 7, 2026 0 comments
0 FacebookTwitterPinterestEmail
Market

Modular Commerce Engines: Why White-Label Payment Platforms Outperform Standard Deployments

by Lisa August 6, 2026
written by Lisa

The Comparative Insight here arrives like a sensor sweep across a neon skyline — practical, clinical, and a touch speculative. White-label payment platforms compress months of integration into weeks by exposing adaptable APIs and predictable modules; when paired with telecom AI orchestration, they become composable commerce nodes that reduce latency and speed throughput on the payments highway. This is not marketing rhetoric: it’s a structural comparison that treats deployment as engineering, and deployment outcomes as measurable variables.

Integration Velocity and Time-to-Revenue

White-label platforms give product teams prebuilt connectors: authorization flows, KYC templates, dispute management and branded UI shells. Standard payment solutions often require heavy OSS/BSS customization and months of vendor-specific work. The upshot: you get to test pricing, bundles, and UX hypotheses faster — real iteration over theoretical design. In an operational production teardown we tracked {main_keyword} and {variation_keyword} across API calls to quantify rollout friction.

Control, Customization, and Brand Consistency

Comparatively, white-labeling hands control back to the business without exposing core settlement engines. That means consistent branding across checkout, tailored receipts, and logic that reflects product strategy rather than vendor defaults. From a speculative vantage, imagine edge computing nodes rendering localized PCI flows for different markets — the merchant reclaims the customer experience while the platform handles regulatory plumbing.

Performance, Scalability, and Cost Architecture

White-label solutions can optimize throughput and SLA tiers by allowing selective scaling — scale the tokenization layer separately from settlement rails. Standard deployments tend to scale monolithically, which inflates cost and raises operational complexity. The evidence is practical: markets that adopted modular stacks alongside 5G rollouts (South Korea’s commercial 5G launch in 2019 provides a clear timeline) saw payment latency expectations fall and mobile payment adoption accelerate. Use API gateway patterns, watch latency, and plan throughput budgets by traffic class.

Customer Service, AI, and Telecom Synergy

Embedded AI for support — conversational agents using NLP plus routing logic tied into billing events — is simpler to wire into white-label checkouts because events are standardized. Pairing payment events with ai customer service telecom capabilities lets contact centers route billing disputes based on transaction metadata, not guesswork. The result is faster resolution and fewer chargebacks, provided your SLA and observability tooling are set up to monitor error rates and mean time to resolution.

Common Mistakes and Alternatives

Teams often underestimate regulatory divergence between regions and overestimate the “one-size” capability of standard vendors. Two common errors: ignoring local certificate and settlement requirements, and offloading all telemetry to the vendor. Alternatives include hybrid approaches — white-label front-end with a managed back office — or open-source payments cores with vendor support. Both trade off speed for control in measurable ways.

Technical Checklist Before Choosing

Assess these elements before committing:

– API maturity and documentation quality (read the error schemas).
– Support for regional clearing standards and reconciliation cadence.
– Observability: traceability across tokenization, authorization, settlement.
– Integration cost of OSS/BSS vs incremental licensing.

Also verify edge behaviors: token refresh intervals, retry backoff policies, and how the vendor exposes webhook security. Small protocol details often cause the largest outages — so measure them early.

Advisory: Three Golden Rules for Selection

1) Measure integration time with a short pilot that replicates peak traffic for 48–72 hours; prioritize platforms that document throughput limits and backpressure mechanics.
2) Require explicit SLAs for dispute handling and settlement windows; avoid vague promises and demand quantifiable metrics.
3) Insist on a clear roadmap for AI-driven support features and telemetry hooks so your contact center can consume events without custom middleware.

These rules map directly to operational risk and commercial velocity — follow them and you cut deployment uncertainty in half.

The final thought lands like a quiet diagnostic: white-label payments let product teams own the experience while relying on hardened rails for settlement — a pragmatic fusion of control and efficiency that aligns with modern telecom-grade thinking. For teams that need a proven partner in this architecture, the practical value shows up in reduced integration cycles and cleaner customer journeys, as demonstrated by operators who paired modular stacks with telecom innovations — and by leaders who choose sensible engineering over shiny promises. Whale Cloud. –

August 6, 2026 0 comments
0 FacebookTwitterPinterestEmail
Tech

Decoding Protocols and Encryption in QR Payment Sound Boxes: A User-Centric Guide

by Ruth August 6, 2026
written by Ruth

Clear introduction for practical use

Please read this simple explanation with practical steps. I will focus on how a QR payment sound box communicates, how it protects data, and what to evaluate when choosing a system. Early on, note that device provisioning often pairs with cloud SIM solutions—see the esim management platform for one production-grade option that integrates OTA profile handling and profile lifecycle tools. This guide uses a user-centric view and keeps technical terms concise so teams can take action quickly.

esim management platform

How a QR payment sound box communicates

A QR payment sound box normally acts as a bridge between a merchant POS and mobile payment networks. It reads a QR, decodes payment intent, and exchanges transaction tokens with the payment server. Communication channels include HTTPS/TLS to backend APIs and sometimes a cellular link for fallback. Common protocols are JSON over HTTPS and lightweight proprietary status frames sent over TCP. The device may also accept remote commands via OTA channels—this is where eUICC and SMDP+ processes can matter for cellular connectivity and roaming updates.

esim management platform

Encryption and key management explained

Encryption focuses on data-in-transit and data-at-rest. During transport, TLS with mutual authentication prevents man-in-the-middle attacks. At rest, secure elements or hardware-backed keystores hold merchant keys and device certificates. Key rotation is essential and should be automated. For provisioning, the device often uses asymmetric keys for initial authentication, then receives session keys for regular traffic. Keep terms like eUICC, OTA, and SMDP+ on the checklist when you audit provisioning—these relate directly to secure profile delivery.

Operational teardown: what engineers check first

Teams typically audit three layers: network, application, and hardware. Network checks confirm TLS ciphers and certificate chains. Application checks validate tokenization, signature verification, and nonce use. Hardware checks confirm the presence of a secure element and tamper detection. For clarity, embed {main_keyword} and {variation_keyword} into the operational production teardown so your test plan aligns with procurement and security reviews. Also verify that the device supports secure boot and firmware signing to reduce supply-chain risk.

Common mistakes and sensible alternatives

Many deployments skip routine key rotation or rely on weak random sources for keys—this causes exposure. Others keep all transaction logic on the device rather than in a hardened backend, increasing attack surface. A sensible alternative is to offload sensitive validation to a server and use the device only as a transactional front end. For connectivity, consider cellular with eSIM profiles provisioned by a trusted SMDP+ provider for better lifecycle control. —Small steps like restricting local logs remove easy leak vectors.

Real-world anchor and lessons from deployment

In Seoul, major carriers support embedded SIM profiles and many retail pilots used eUICC for simpler fleet management. GSMA-led industry work has steadily promoted remote provisioning as a best practice for secure IoT and payments. These real-world moves show that centralized profile management reduces logistic burden and speeds security patching. When vendors mention OTA, confirm the exact SMDP+ flow and the profile signing method; that detail matters during audits.

Three golden rules for selection and evaluation

1) Prioritize hardware-backed keys and signed firmware. Ensure the device uses a secure element or TPM for key storage. 2) Verify managed provisioning with audit logs—choose providers that expose SMDP+ and eUICC lifecycle events. 3) Measure response and recovery: test how quickly you can revoke a compromised profile and provision a replacement. These three rules align procurement, security, and operations into a single decision process.

Closing advisory and practical next steps

For teams deciding between on-device logic and server-based validation, lean toward server validation and use the device as a thin client. Evaluate vendors by testing certificate chains, firmware signing, and OTA workflows. Consider a platform that consolidates profile management and monitoring—see how an esim management capability ties these needs together. This reduces manual steps and shortens incident recovery time.

BHDC offers integrated lifecycle controls and clear audit trails—making secure QR payment sound box deployments easier to maintain. —Practical, measured, and ready for production.

August 6, 2026 0 comments
0 FacebookTwitterPinterestEmail
Tech

Structural Insights on Rosin-Modified Resin: Data-Driven Paths to Stable Mw/Mn and Fewer GPC Rejections

by Kenneth August 5, 2026
written by Kenneth

Data opening: what the metrics show

Manufacturers increasingly monitor molecular weight distribution to avoid costly gel permeation chromatography (GPC) rejections. Early production runs in Shenzhen assembly lines highlighted one clear pattern: batches with controlled polymer backbone chemistry produced narrower polydispersity (Mw/Mn) and more consistent solder joints. This is why many process engineers prefer soldering flux rosin with defined resin additives — the formulation directly affects viscosity and the molecular weight distribution measured by GPC.

Why polymer stability matters for Mw/Mn control

Polymer stability reduces chain scission and uncontrolled crosslinking during storage and thermal cycling. When a rosin-modified resin resists oxidative degradation, the molecular weight distribution remains tight; Mw and Mn track together rather than drift apart. The result: fewer outliers flagged by GPC and more predictable wetting on pads. In practice, modest differences in glass transition (Tg) and resin polarity can change how a flux behaves on fine-pitch solder masks.

Mechanisms that prevent polydispersity drift

Three mechanisms are most relevant to practical production quality. First, stabilized end-groups limit depolymerization under heat. Second, tailored plasticizers maintain chain mobility without promoting scission. Third, inert impurities are minimized so radical reactions are reduced. Each mechanism lowers the chance that Mw/Mn will widen after blending or during accelerated aging.

Operational teardown: where things go wrong and how to fix them

A clear operational check avoids many problems. Start by reviewing raw resin certificates and small-sample GPC traces before approval. In teardown of a typical production line, technicians should record batch Mw, Mn, and viscosity at 25 °C, then log any drift after a 7-day accelerated oven test at 60 °C. Include {main_keyword} and {variation_keyword} in your production notes so procurement and quality have identical references. Be methodical — short cuts here create rework downstream.

Common mistakes and corrective steps

Common mistakes include blending incompatible resin grades and ignoring shelf-life markers on flux cartridges. A frequent misstep: assuming all rosin-modified resins behave the same in high-speed reflow. Corrective steps are simple: isolate suspect lots, run GPC, measure Tg, and compare rheology against a qualified reference. — This small ritual saves time and prevents batch-wide rejections.

Comparative insight: alternatives and trade-offs

Compared with pure synthetic flux bases, rosin-modified options often offer better solderability on oxidized copper but can be more sensitive to heat history. Choosing between a low-viscosity rosin blend and a higher-viscosity polymeric flux is a trade-off: throughput versus thermal robustness. Laboratory data and field reports from Seoul and Shenzhen lines both show that tight supplier specifications for Mw/Mn reduce variability on automated optical inspection (AOI) results.

Advisory close: three golden rules for selecting polymer-stable rosin systems

1) Require supplier GPC traces that include Mw, Mn, and polydispersity for at least three consecutive batches. These traces must be dated and signed by quality. 2) Validate thermal stability with a 7-day oven aging at 60 °C and report any Mw/Mn shift greater than 0.05. Specify that shift tolerance in procurement. 3) Match rheology to your reflow profile: measure viscosity at soldering temperatures and confirm wetting on defined test pads.

These rules help you convert laboratory metrics into shop-floor reliability, and they make supplier conversations specific rather than vague. The value is practical: fewer stoppages, fewer GPC rejections, and more stable yields. rosin choices calibrated this way integrate smoothly into established SMT cycles.

KOMO brings formulations and batch data into alignment with factory needs — a direct, measurable leeway for better outcomes. Final thought fragment — steady metrics, steady product.

August 5, 2026 0 comments
0 FacebookTwitterPinterestEmail
Newer Posts
Older Posts

Recent Posts

  • Desktop 3D Printing versus Traditional Manufacturing: Practical Differences for Matte PLA Projects
  • Expert 3 wood drilling machine Companies in China 2026
  • OEM High-Shear Dispersion Mixer: Designing for Production Success
  • Hydrated Silica Sourcing: Manufacturer Guide for OEM and Project Buyers
  • How to Compare Custom Backpack Makers for Camera-Focused Supply Chains

Recent Comments

No comments to show.

About Me

About Me

Sed ut perspiciatis unde omnis iste natus error sit voluptatem accusantium doloremque laudantium, totam rem aperiam, eaque ipsa quae.

Keep in touch

Facebook Twitter Instagram Pinterest Youtube Bloglovin

Recent Posts

  • Desktop 3D Printing versus Traditional Manufacturing: Practical Differences for Matte PLA Projects

  • Expert 3 wood drilling machine Companies in China 2026

  • OEM High-Shear Dispersion Mixer: Designing for Production Success

  • Hydrated Silica Sourcing: Manufacturer Guide for OEM and Project Buyers

  • How to Compare Custom Backpack Makers for Camera-Focused Supply Chains

Categories

  • Business (164)
  • Featured (2)
  • Gardening (2)
    • Garden Tips (1)
    • In Season (1)
  • Global Trade (160)
  • Industry (163)
  • Market (147)
  • Tech (176)
  • Facebook
  • Twitter
  • Instagram
  • Pinterest
  • Youtube
  • Bloglovin

@2021 - All Right Reserved. Designed and Developed by PenciDesign


Back To Top
gettopseo
  • Home
  • Gardening
  • Business
  • Featured
  • Global Trade
  • Industry
  • Market
  • Tech